Multi-Provider LLM Strategy for Mid-Market SaaS Companies
Intelligent request routing through a single gateway cuts LLM costs by 30 to 50 percent.
Multi-provider LLM strategy has become the default setup for mid-market SaaS companies in 2026, not a fringe experiment. But routing across providers only pays off, in cost, resilience, and model quality, when it runs through a single gateway layer instead of getting bolted onto each service by hand. If a company skips that layer, it ends up with scattered API keys, no unified read on spend, and outages that cascade the moment one provider has a bad day.
What a gateway layer does and when a team needs one
An LLM gateway sits between the application code and whichever model providers a company uses. Think of it as a control tower: it normalizes the different provider APIs into one interface, holds the credentials, applies spending and access policies, and gives engineering one place to watch what's actually happening across every model call.
The architecture that makes this work splits into two layers. A control plane handles authentication, authorization, and rate limiting. A data plane handles the actual request forwarding. Keeping those separate matters because governance doesn't slow anything down: one gateway benchmark clocked the added latency from this layer at 11 microseconds per request under sustained load of 5,000 requests per second. That's the kind of overhead nobody notices.
What a gateway built for production actually does, day to day:
- Reroutes traffic automatically when a provider errors out or hits a rate limit, with zero code changes on the application side
- Manages one set of virtual keys instead of provider-specific API keys pasted into a dozen different services
- Caches semantically similar queries so a repeat-ish question returns in under 5 milliseconds instead of waiting several seconds for a fresh model call
- Enforces budgets and per-team rate limits before spend gets out of hand, not after finance sees the bill
- Logs every request in enough detail to break down latency, error rates, tokens, and cost by team, model, and provider
There are two honest signals that a team has crossed into needing this. First: retry-with-backoff logic gets copy-pasted into more than two services, because everyone's solving the same failover problem separately. Second, and more telling: nobody can answer a simple question like "what's this month's LLM spend, by feature" without pulling numbers from three different dashboards. Before those signals appear in the data, a gateway just adds a layer of indirection for no real benefit. This is a timing decision, not a box to check off a features list. The middleware category itself isn't early-stage anymore. Growth projections put the market's expansion rate near 50% annually through the next decade, and a sizable share of enterprises, somewhere around four in ten, already run some kind of middleware layer to manage their AI infrastructure.
The cost and quality case for routing across providers rather than defaulting to one
Start with the price spread, because it's the whole argument in one number. A million output tokens on a budget model running off-peak can cost under a dollar. The same million tokens on a frontier-tier model can run well over a hundred dollars. That's not a small efficiency gap, it's closer to two orders of magnitude, and it means the model a team defaults to matters more than almost any other infrastructure decision they'll make this year.
Enterprise spend on LLM APIs roughly doubled within about a year, moving from the low billions into the high single-digit billions industry-wide. At that scale, routing keeps an AI budget sane or lets it blow past finance's plan every quarter, because unmanaged spend grows too fast for manual oversight to catch it.
The core routing idea is simple: send each query to the cheapest model that can actually handle it, and reserve the expensive model for the queries that need it. Academic research backs this up with real numbers. One widely cited study out of UC Berkeley, Anyscale, and Canva, published at ICLR 2025, built a routing system that cut costs by over 85% on a standard benchmark while keeping 95% of top-tier model performance, and it did that by sending only 14% of queries to the strong model. A separate Stanford project on cascade routing showed cost reductions as high as 98% under the right conditions. Another study, published through ACM, found that adaptive routing across several reasoning benchmarks matched or beat the best single model's accuracy while cutting API costs by up to 60%.
Those benchmark numbers are exactly that, benchmark numbers. The 85% figure came from a standard chat benchmark, not from any particular company's actual mix of easy and hard queries. Real savings depend entirely on how a given product's traffic breaks down between simple lookups and genuinely hard reasoning tasks. A support chatbot answering FAQ questions will save far more from routing than a legal-research tool where nearly every query is hard.
Cost isn't the only upside. Research on dynamic routing and model cascading makes the point that routing, done well, can actually beat the single best model on quality, not just save money, because different models have different strengths and a routing layer can match queries to whichever model handles that specific type of task best. Teams that stick with one provider across the board aren't just overpaying. They're also leaving accuracy on the table wherever a specialized model would've outperformed their general-purpose default. Gateway-level routing, combining automatic model selection, policy rules, and live spend tracking, cuts total token cost by 30 to 50% in practice, a reasonable range to hold a team to when setting internal targets.
Five routing strategies a gateway must support in production
Five distinct routing strategies appear across production gateway deployments, and each solves a different problem.
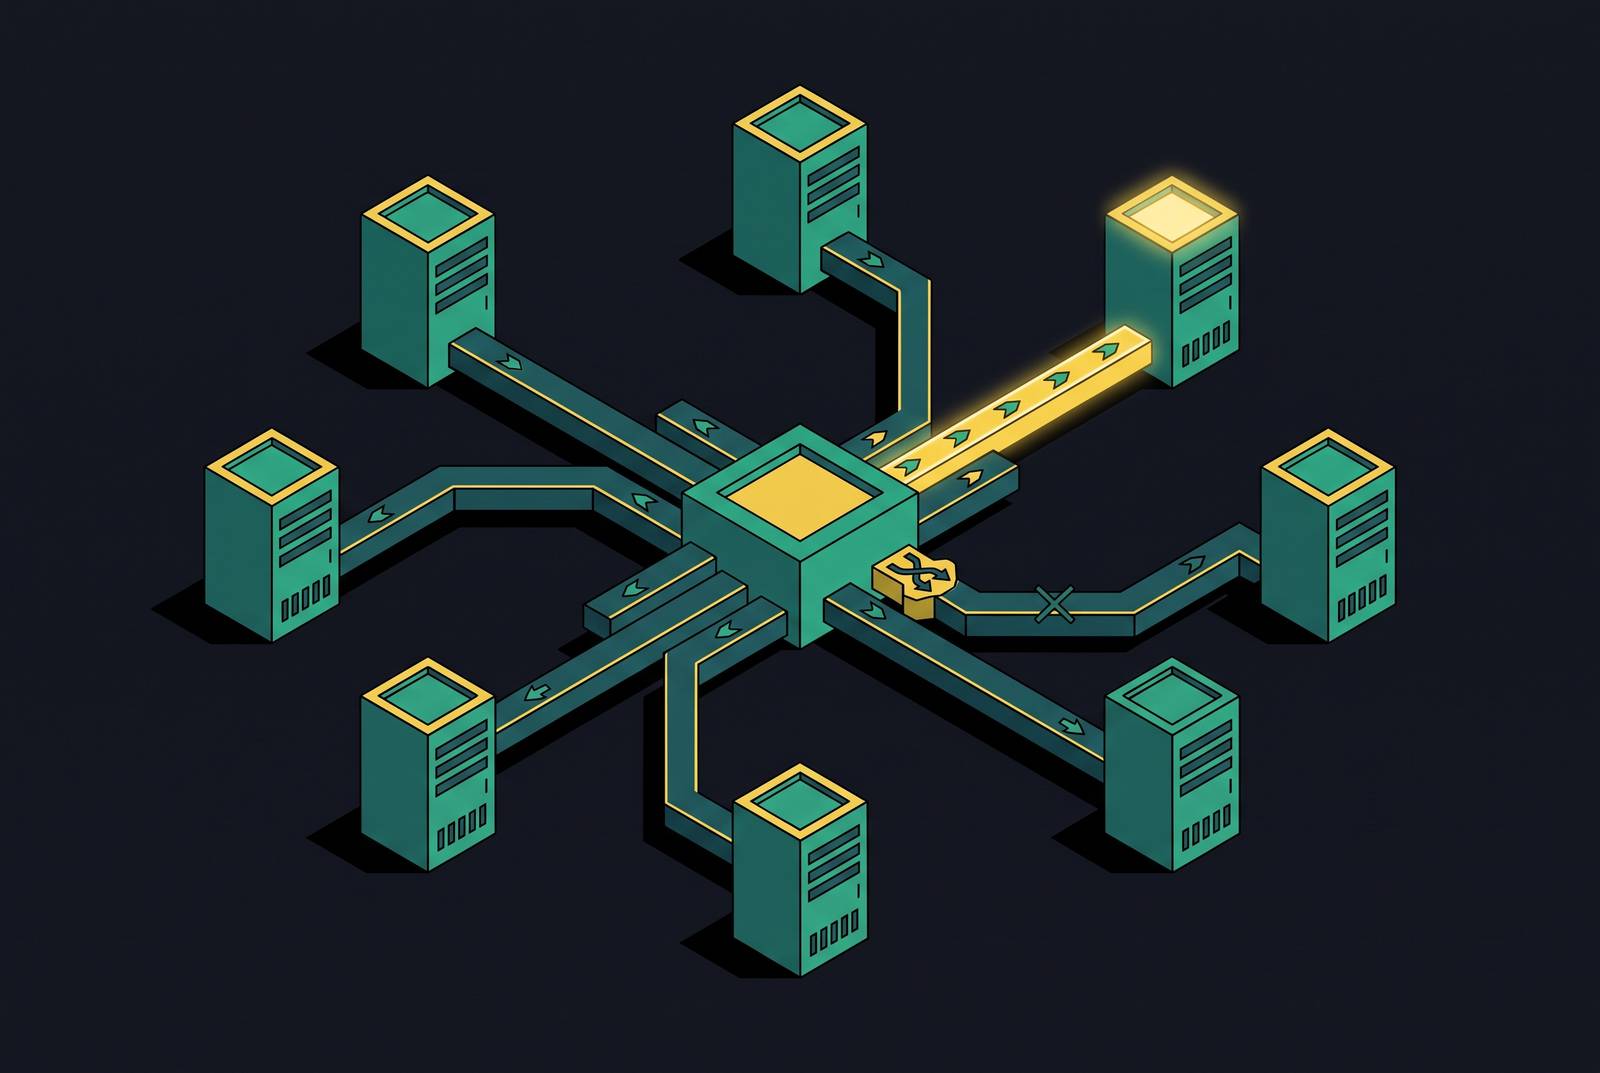
Automatic failover routing retries a request on a backup provider or model the moment the primary one fails, without the application code knowing anything happened. This is the baseline strategy, and it's usually the first reason a team adopts a gateway.
Weighted load balancing spreads traffic across providers or API keys according to configured weights. It's useful for staying under rate limits, and it's also how a team gradually shifts traffic to a new provider during evaluation, instead of flipping a hard switch and hoping.
Latency-based adaptive routing sends requests to whichever provider is currently performing best, based on live metrics rather than a static assumption. This matters most in user-facing features, and it matters even more in agentic workflows, where a slow response at step three delays everything after it.
Cost-aware routing shifts traffic toward cheaper providers as a budget gets consumed. This is where the price-gap argument from the last section actually gets enforced as policy, rather than left to whichever developer remembers to check the pricing page.
Conditional and compliance-based routing sends requests to specific providers or regions based on tier, team, or data-residency rules. This is the strategy that makes multi-tenant products and regulated-industry deployments actually workable, since it lets a company guarantee, structurally, that certain data never leaves a certain region.
Semantic routing classifies what a query is actually asking for and routes based on intent rather than a fixed rule. A simple factual lookup goes to a budget model; a multi-step reasoning task goes to a frontier model, and the application layer never has to know the difference.
Why does this matter more now than it did two years ago? Agents. A single coding task or research task run by an autonomous agent can trigger hundreds of sequential model calls. Routing decisions that were basically trivial for one-off chat queries become serious cost and latency drivers once they're multiplied by a few hundred calls in a single pipeline. The design principle that holds all five strategies together: routing logic belongs in gateway configuration, not scattered across a dozen services. Change a routing rule once; every service that touches a model should reflect it immediately.
How token spend breaks traditional SaaS procurement, and its replacement
AI token spend for businesses grew by several times over year over year, according to payments data drawn from tens of thousands of businesses. That's not a gradual budget creep, it's the kind of growth curve that breaks whatever spreadsheet was tracking it in January.
Industry survey data backs up how common the overshoot problem is: a large majority of companies exceeded their original AI cost projections, and individual agentic AI projects, on average, ran over budget by more than double what was planned. This isn't a handful of outlier teams underestimating. It's systematic, and it's happening because per-token pricing behaves nothing like the per-seat SaaS pricing procurement teams built their processes around.
A few reasons this breaks traditional procurement:
- Costs scale with usage the company doesn't fully control, including how its own customers use AI-powered features inside the product
- There's no fixed per-seat number to forecast against, so usage spikes stay invisible until the invoice lands
- Splitting spend across teams, features, and customers takes instrumentation that most provider billing dashboards simply don't offer
A separate SaaS management survey found AI-native spend more than doubling year over year overall, and nearly quadrupling inside large enterprises. Most IT leaders in that survey reported unexpected charges tied to usage-based pricing, and a significant share said they'd cut a project specifically because SaaS costs came in higher than planned.
A gateway replaces the reactive spreadsheet with something closer to real infrastructure. Virtual keys get issued per team, per project, or per customer, each with a hard budget cap, so one team's runaway agent can't quietly drain another team's allocation. Cost attribution happens in real time, by model, provider, team, and feature, instead of getting reconstructed after the fact from a billing export. Policy enforcement caps calls to the pricier models at a threshold someone actually set on purpose, rather than relying on every developer remembering to check.
Analyst projections put worldwide spending on AI models and platforms growing more than 60% in 2026 alone, landing in the tens of billions of dollars. This isn't a problem that resolves itself as the market matures. It gets bigger. Finance and security stakeholders need to see this spend in a form they can actually act on, and a dashboard engineering built purely for its own debugging purposes usually isn't that form. The gateway's observability layer needs to be legible to someone who's never read a token count in their life.
Keeping production AI reliable when providers fail or degrade
Teams running more than one provider tend to see uptime near 99.99%, according to guidance on multi-provider orchestration. Single-provider setups don't get that safety net: when the one provider a company depends on goes down, the product goes down with it, full stop.
The instinct to handle this with application-side try-catch blocks is understandable, and it's also brittle. Provider-switching logic embedded directly in service code has to be updated every time a provider changes its API, and fallback behavior ends up inconsistent from one service to the next because nobody wrote it the same way twice. A gateway-level fallback chain solves this by getting configured exactly once and applied everywhere, uniformly, with the application code, prompts, and response handling never touched. A request aimed at one model can fail over to that same model hosted by a different provider, or to an entirely different model, based on whatever priority order got configured ahead of time.
Reliability and cost governance aren't separate concerns here, either. If a failover routes a request to a pricier backup provider, that overage needs to appear in budget tracking immediately, and the same spending policies need to keep applying. Reliability can't become a quiet backdoor around cost control. Teams that skip the gateway layer entirely tend to see token spend climb 30 to 40% faster than it needs to, according to one production comparison, on top of carrying much larger operational risk whenever a provider has an outage.
On overhead: because the architecture keeps auth and rate limiting in-memory and separate from the actual request path, the reliability layer itself doesn't meaningfully slow anything down. Worth noting that a lot of vendor benchmarks comparing gateway throughput get run on mocked backends under lab conditions, and one such benchmark reported throughput differences of several hundred percent between competing gateways. In a real production workload, the model's own inference time so thoroughly dwarfs gateway processing time that those ratios mostly don't translate into anything a user would notice. Architectural fit, meaning how well a gateway's routing and failover model matches the actual production setup, matters more than a synthetic throughput number ever will.
Data security and compliance requirements that belong in the gateway, not in application code
Once requests start routing across several different providers, the compliance picture gets complicated fast. Each provider has its own data handling terms, its own regional data residency options, and its own audit log format, and trying to track all of that per-provider, per-service, doesn't scale past a handful of integrations.
A handful of things belong squarely in the gateway rather than duplicated across every service:
- PII, PCI, and PHI redaction, applied before any data reaches a model provider, and reviewable rather than a black box nobody can audit
- Compliance-based routing that sends sensitive requests only to providers and regions cleared for that data, enforced automatically at the policy layer instead of depending on a developer remembering the rule
- Role-based access control by team, project, and key, governing who can call which models, how much, and against which budget
- Audit logs that satisfy standards like SOC 2 Type II and HIPAA from day one, not bolted on later as a paid add-on
- Key rotation and revocation that doesn't require a deployment, so a compromised key gets shut off in minutes, not during the next release cycle
None of this is exclusive to large enterprises. A mid-market SaaS company holding customer data carries the same regulatory exposure as a much bigger company, just with less staff to manage it. A gateway architecture makes that exposure manageable without forcing a team to build a custom security layer for every single provider it adds.
Some managed aggregation services route requests across providers without disclosing which provider or model actually handled a given request. That opacity is flatly incompatible with any compliance regime that requires knowing exactly where a piece of data went. If a company can't answer that question, it hasn't solved compliance, it's just moved the risk somewhere less visible.
Evaluating and choosing a gateway in the current market
Reliability comes first. If downtime on an AI feature is unacceptable to the business, and for most customer-facing products it is, automatic failover and multi-provider support aren't optional line items to compare on a feature chart. They're the entire reason to adopt a gateway in the first place, and a vendor without solid, provable failover shouldn't make the shortlist regardless of what else it offers.
Cost visibility comes next, and it needs to be granular. A gateway that can only report total spend, without breaking it down by team, feature, and model, doesn't actually solve the procurement issue described earlier. It just moves the spreadsheet one layer up the stack.
Compliance support needs to match the regulatory environment a company actually operates in, not some generic enterprise checklist. A healthcare SaaS company needs audit logging and data redaction built to the standard its regulatory environment demands. A company that never touches health or payment data has a lighter bar to clear, and shouldn't overpay for compliance features it will never use.
Provider breadth matters, but less than the first three. A gateway that supports a wide range of models and providers gives a team more room to route intelligently as pricing and model quality shift, and both change constantly. Model performance and provider pricing that look optimal today won't necessarily hold in six months, and a gateway that locks a team into a narrow set of providers limits how much of the cost and quality argument made earlier a team can actually capture.
Finally, weigh vendor stability alongside technical fit. The market for this category is moving fast, with new entrants, acquisitions, and consolidation reshaping the competitive field regularly. A team choosing a gateway today should factor in how mature and how stable a given vendor's business looks, not just how its feature list reads on a pricing page. Technical fit that comes attached to a vendor in flux is a real risk, even when the product itself performs well in evaluation.