Comparing Automatic PII Redaction Tools That Enforce Sanitization Before LLM Provider Submission
Seven criteria separate PII redaction tools that protect data before LLM submission.
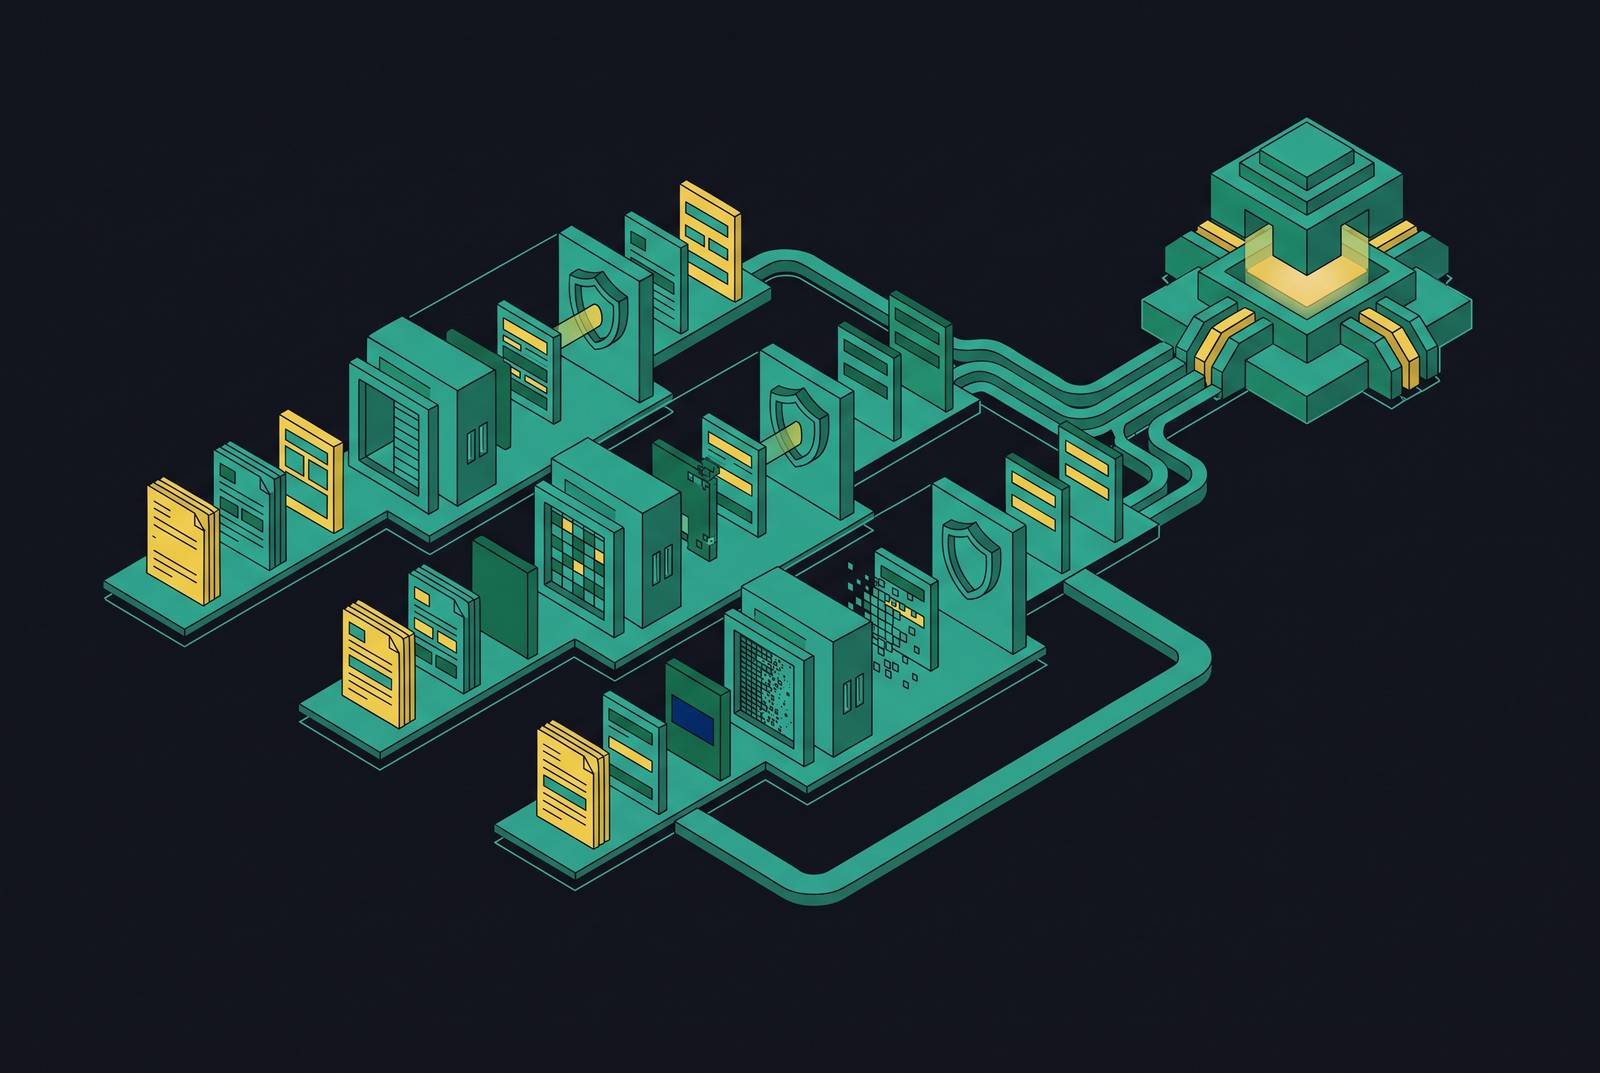
To automatically strip PII and PHI before sending prompts to OpenAI or another model provider, place an enforced redaction layer before the outbound API call. Compare tools on seven criteria beyond detection claims alone, because coverage, actions, reversibility, scope, audit trails, latency, and deployment affect sensitive-data protection. A HIPAA compliant AI gateway requires an acceptable data boundary and contractual safeguards alongside a redaction feature.
Why prompts need sanitization before they reach an LLM provider
Transmission is the first exposure. Providers process prompts on infrastructure outside the sending organization's control, so the organization has third-party data-handling obligations when it sends personal data. Cyberhaven's 2026 AI Adoption & Risk Report found that sensitive data is part of 39.7% of all enterprise AI interactions. The boundary is crossed routinely.
Models do not classify sensitivity before accepting tokens. A credit card number and a city name are both prompt content, and storage controls cannot undo the act of sending them. WSO2's PII redaction guide identifies retrieved context, tool-call arguments, MCP results, and responses as additional exposure surfaces. To prevent this each time, a tool must enforce sanitization at the boundary, before the API call leaves.
The seven criteria that distinguish pre-submission PII redaction tools
Detection coverage is the first criterion, including supported entity types and engines for structured identifiers, names, and credentials. Actions on match are the second, distinguishing detect-only, block, and redact. Detect-only does not prevent the sensitive payload from leaving. Enforcement scope is the third, which covers prompts, responses, and structured tool traffic. Reversibility is the fourth, determining whether removed values can return for authorized workflows.
Audit trail is the fifth criterion, including identity, detected entity, action, and timestamp. Latency is the sixth, because detection overhead compounds across chained agent calls. Deployment model and data boundary are the seventh, which show who gets the raw text before sanitization. None deserves the same weight in every setting. Together, these criteria provide the scorecard for comparing the tool categories below, including where a documented feature leaves an integration responsibility unresolved.
How detection engines work and where each falls short
Regex works well for identifiers with predictable formats, including email addresses, SSNs, card numbers, and IP addresses. It is fast, deterministic, and easy to audit. With in-process detection, there is no network hop, and regex scanning can add under two milliseconds. However, patterns cannot reliably identify names or locations and become brittle with international or non-standard identifier formats.
NLP and named entity recognition, or NER, look for free-text entities such as names and addresses. Microsoft Presidio and Azure AI Language PII use this approach. Context comes at a runtime cost, though. Analyzer calls grow slower with larger payloads, while accuracy can degrade on short inputs, uncommon names, and non-English text. Model-based scanners can add hundreds of milliseconds to seconds per scanner.
Secret scanners cover credentials that ordinary PII templates and NER models are not designed to catch, including access tokens, JWTs, connection strings, and private keys. These scanners can run quickly in-process. Maxim AI's gateway PII comparison explains why combining engines is the production approach. No single detector handles structured identifiers, names, and credentials well enough to stand in for all three.
Redaction modes and what each means for compliance and workflow
Blocking rejects the workflow, while redaction forwards a changed payload. Gravitee's AI gateway documentation describes placeholder replacement and blocking above configured sensitivity thresholds.
Irreversible masking removes values without retaining a restoration path. It also gives up any personalization that needs those values. Removing a matched span, however, does not by itself establish that the remaining record cannot identify someone. Reversible tokenization preserves a mapping for authorized restoration, so it is pseudonymization rather than anonymization and remains regulated under GDPR.
Grepture provides a concrete reversible workflow, tokenizing PII outbound and restoring it on return without custom token storage. Limina supports realistic synthetic substitutions and a redact-call-re-identify loop, preserving more natural prompt content than typed placeholders. Skyflow instead keeps real values in a vault and sends tokens to the model. That design changes the isolation boundary, but teams still need to check logs separately with every mode.
Enforcement scope — why scanning only the prompt is not enough
Lyzr's 2026 tool survey identifies five surfaces, namely user input, retrieved context, tool-call arguments, model output, and logs. Typed input is only one entry point. Harmonic Security's analysis of GenAI prompts in Q2 and Q3 2025, cited by the survey, found disproportionate sensitive-data exposure in documents and pasted records. Sanitizing a short question does not sanitize the records added to answer it.
Responses create a separate risk because models can retrieve, infer, or hallucinate identifying information absent from the prompt. Tool-call JSON and MCP arguments also pass identifiers and records between tools and sub-agents. Plain-text scanning does not establish structured-payload coverage. Maxim AI's comparison treats response scanning as a differentiator among gateways. For agentic or RAG workloads, response scanning and tool-call coverage therefore belong among the non-negotiable criteria.
Full AI gateways with built-in PII enforcement
A gateway can apply one policy across traffic routed through it, combining routing, governance, and sanitization without application-code changes. Bifrost, Maxim AI's open-source Go gateway, combines regex PII detection, 222 built-in secret rules, Presidio integration, and Azure detection. It supports detect, block, and redact across prompts, responses, and MCP tool arguments.
Bifrost separately configures redaction for live traffic, gateway logs, and trace exports. It supports self-hosted, in-VPC, and on-premises deployment. Maxim AI's documentation describes immutable per-request logs with identity, team, key, model version, token usage, and latency as supporting SOC 2, HIPAA, and GDPR frameworks. The detector a team chooses still affects performance and the data boundary, especially when an external analyzer gets the raw text.
LiteLLM is an open-source Python proxy using separately deployed Presidio Analyzer and Anonymizer containers. It supports entity-level masking or blocking and scans prompts and outputs. That adds containers for teams to operate. A March 24, 2026 PyPI compromise affected LiteLLM, so security-conscious teams should verify pinning practices. Kong AI Gateway instead offers an Enterprise-only Docker-based anonymizer with placeholder or synthetic replacement, with response scanning available from version 3.12.
Hosted gateways make a different operational tradeoff. OpenRouter offers regex presets and Presidio-based NLP presets described as in beta, but its sensitive-information guardrail is input-only. Cloudflare AI Gateway uses predefined and custom DLP profiles in both directions, with documented actions limited to flag or block. Both process traffic on hosted infrastructure. Gravitee AI Gateway introduced its PII Filtering Policy in version 4.11, covering prompts, responses, MCP, and LLM proxy traffic through a configured redaction model whose selection affects accuracy.
Specialist PII redaction APIs layered in front of a gateway or application
Specialists can offer deeper detection or language support, but the integration must enforce where scanning happens. Presidio is an MIT-licensed, self-hosted Python SDK combining regex, checksums, deny lists, and NER, with custom recognizers. It lacks built-in secret scanning, reversible redaction, and an audit trail. The application team still has to add those controls. Model choice and compute requirements also determine operating cost and latency.
Grepture is an open-source network proxy available self-hosted or as managed SaaS in Frankfurt. Its regex detection runs under two milliseconds and supports 30+ secret and credential pattern types. Native outbound tokenization and return-path restoration avoid building that loop separately. It works across languages and frameworks, unlike a Python-only library. Broader audit and structured-payload requirements still belong in the evaluation.
Limina, formerly Private AI and rebranded in 2026, covers PII, PHI, and payment data in 52 languages. Its transformers are trained for high recall, with a focus on healthcare entities. Deployment is a customer-VPC container or hosted API, with enterprise pricing requiring sales engagement. Skyflow takes the vault route instead, supporting authorized rehydration and, according to the survey, MCP and agentic workloads on AWS. Vault tokens provide strong isolation but require application flows to be redesigned around them.
As applications grow, each integration must keep scope, logging, and restoration controls in place and cover all other paths. That engineering burden is the main tradeoff against a gateway. Cloud-native services reduce some operational work, but narrow the boundary they cover.
Cloud-native managed detection for teams already inside a single provider
Amazon Bedrock Guardrails integrates managed PII detection into Bedrock invocations and can block or mask detected values. It requires no separate detection infrastructure to operate. Its enforcement path does not cover prompts sent directly to other providers. Google Cloud Model Armor similarly supplies managed guardrails, including PII detection, within Google Cloud's model invocation surface.
Azure AI Language provides NER-based detection as a standalone API and as an analyzer used by gateways such as Bifrost. It is not a complete proxy enforcement layer. Cloud detection calls add latency and send the original text to the cloud endpoint before redaction. These services are a better fit for teams already in that cloud than for teams using more than one provider, where network boundaries are the main limit.
How deployment model determines who processes unredacted data
A hosted redactor must see the original text to sanitize it. That makes deployment both an infrastructure choice and a data-processing question. Regulated teams must assess authorization and whether the required DPA or BAA is in place.
Self-hosted options include Bifrost, LiteLLM, Presidio, LLM Guard, and Limina's customer-VPC container. Skyflow also supports a vault deployed in a VPC. When detection stays within the organization's network, raw text stays out of a hosted analyzer, but teams must handle availability, scaling, and updates. A self-hosted proxy still has that external boundary when it uses an external detection API.
Zero Data Retention is a separate contractual property. It must be verified rather than inferred from deployment or redaction claims, including its treatment of gateway storage and provider logs. Fully disconnected environments require self-hosted tools. Hosted gateways cannot provide an air-gapped processing path.
Audit trails, log redaction, and what compliance teams will actually ask for
A sanitized provider call can coexist with an unsanitized gateway log. That leaves a long-lived copy exposed to discovery. Maxim AI's comparison names three copies that teams need to check separately, including the live call, the gateway request log, and exported traces. Bifrost exposes separate redaction configurations because changing one copy does not sanitize the others.
A compliance or DPO inquiry needs the detected entity types, action, policy version, authenticated user or team, timestamp, and model version. It also needs to establish whether the evidence contains the original value. Auditability must not become another raw-data repository. Tamper-evident, append-only records support compliance evidence in ways editable application logs cannot, without making a log feature alone proof of compliance.
Policy scope also needs to reflect who handles which data. A PHI workflow may need stricter rules than an internal engineering tool, so it helps to have per-team or per-key controls. WSO2's tutorial content places gateway audit output within broader API governance. OpenTelemetry or direct SIEM exports can make decisions queryable in existing security tools, provided those exports are sanitized too.
Applying the framework — how to match tool category to team profile
Select a category before comparing individual products in depth. A regulated multi-provider team without proxy operations capacity should prioritize an acceptable managed boundary with a BAA where required, bidirectional scanning, audit evidence, and contractual ZDR. A team already inside one cloud can consider its managed guardrails if that invocation path covers the workload.
Python-first teams that need custom entities should look at Presidio or LLM Guard and budget for the engineering work needed for restoration, audit logging, and infrastructure. These are not necessarily drop-in enforcement systems. Teams already using Kong should look at the Enterprise option and check that their installed version supports response scanning, which is available from 3.12 onward. Multilingual or healthcare-focused teams should weigh Limina's language coverage, PHI detection, and synthetic substitution against enterprise pricing and setup effort.
Teams that need to keep real values out of intermediate layers should look at Skyflow's vault architecture and accept the need to redesign the token flow. That requirement changes the shortlist more than a detector benchmark does. Across profiles, composing a production pipeline can require engineering weeks, while integrated enforcement can reduce that work. The durable decision aid is the seven-criterion scorecard, which applies to new tools without depending on a ranking that the next release may overturn.