The Tagging Architecture That Turns One Provider Invoice Into Team-Level AI Spend Clarity
Real-time cost tracking turns shared provider bills into actionable team spending data.
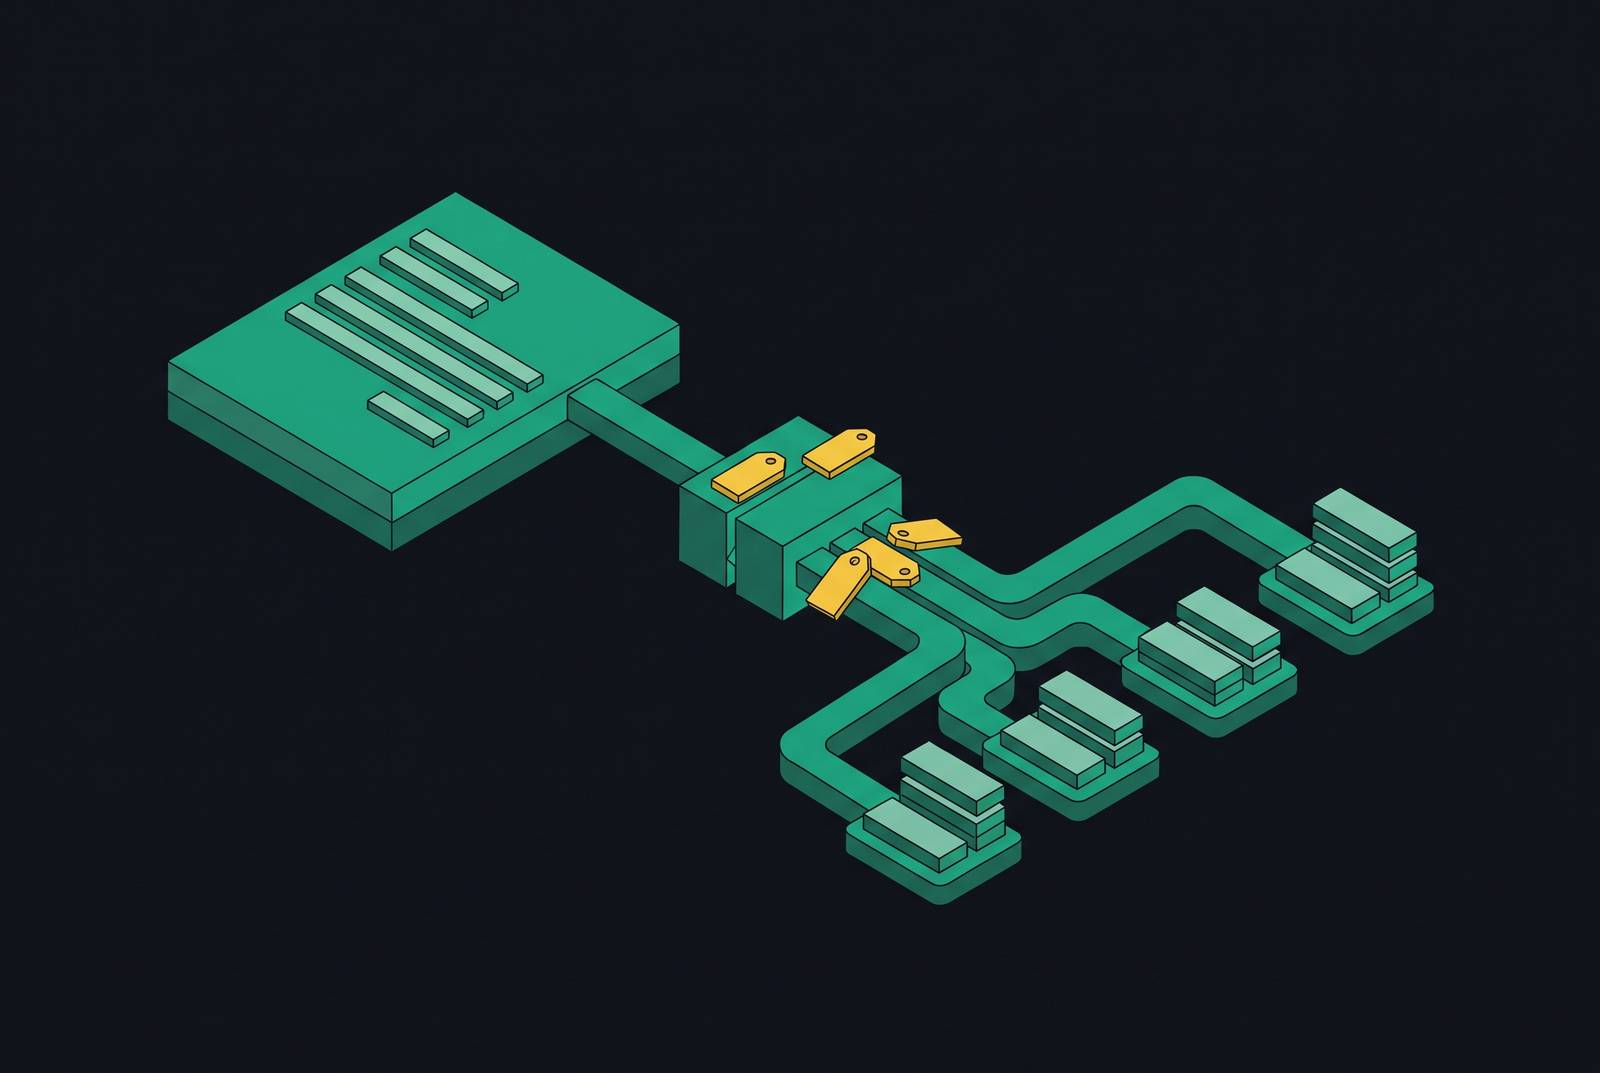
Tracking AI spend in real-time by team, project, model, and provider needs request-level attribution before traffic reaches a provider. A gateway that enriches every request with ownership, key, and routing metadata is the reliable enforcement point for that attribution. Its accounting records turn a shared provider invoice into continuously available cost data that teams can use for budgets and routing decisions.
Why provider invoices are structurally blind to how AI work actually happens
A provider invoice groups charges under billing organizations or projects, with API keys identifying the callers. Provider dashboards can break usage down by model and key, but those dimensions do not identify the teams or workflows behind shared credentials. One key may serve customer support, a coding assistant, a batch-classification pipeline, and an internal agent. Their owners and budgets can be entirely different. Finance therefore receives a total that engineering must reconstruct into organizational meaning after the fact.
The missing information belongs to the caller. Providers cannot infer whether a request belongs to a product feature, an experiment, or another team's production workflow. Better provider reports cannot bring back context that the accounting system never received.
Why tagging cannot be done reliably in application code
When each service adds metadata, enforcement depends on every caller following the same contract. A request without team_id can still succeed, so functional correctness does not establish accounting correctness. No one sees the gap until someone checks the costs. Even correctly tagged services can diverge over time, with one sending team, another sending team_id, and another omitting the field. The reporting layer then needs manual reconciliation before its totals can be trusted.
A shared SDK reduces duplication but does not create a universal enforcement boundary. Agents, third-party integrations, and experimental services can bypass it, while schema changes depend on teams upgrading their callers. Application code says what one application should do. It cannot enforce one policy across independent applications. Reliable attribution requires a control point outside those applications.
What the gateway layer is and why it is the right enforcement point
An LLM gateway is a reverse proxy between application services and model providers, exposing one endpoint for traffic destined for multiple providers. When all model requests pass through it, the gateway sees each caller before any provider receives the request. A new service or integration enters the same policy path rather than implementing its own version of the rules.
The gateway must also understand token-based billing and model differences, because request counts alone do not describe AI costs. Its role extends beyond forwarding ordinary API traffic. It holds provider credentials centrally, allowing applications to use gateway-issued credentials. Ownership metadata can consequently be attached and validated at the same point where the caller is authenticated. Uniform attribution depends on routing all traffic through that boundary.
Designing the tag schema and why each field earns its place
Fields should be chosen against concrete reporting questions. team_id identifies the accountable owner for showback or chargeback, while project identifies the feature or initiative consuming that team's budget. environment separates production from staging and development so experimental usage does not distort production analysis. Each field answers a different budget question. model and provider, already known by the routing layer, complete the minimum schema needed to compare ownership with the resources used.
Additional fields earn their place when the workload requires finer attribution. feature separates capabilities within a project, and customer_id supports customer-level margin analysis or usage-based billing. agent_id makes individual production agents distinguishable, including an agent loop whose activity would otherwise disappear into aggregate usage. More fields are not automatically more useful. Each added field has another value that must mean the same thing in requests and reports.
Schema governance should set out which fields are required, which are optional, and which values are allowed for enumerated dimensions. Requests with missing required metadata should be rejected or quarantined because a default label creates a catch-all bucket that conceals the very gaps attribution is intended to expose.
How can teams track AI costs in real time across models and providers?
The data path begins when the gateway reads request headers or the static metadata attached to a virtual key. Key-bound metadata is more reliable because it enters the request context during authentication rather than depending on application-supplied headers. The gateway then routes the enriched request to the provider. When the response arrives, it reads the provider's token usage fields and associates them with the original tags before returning the response. This handoff preserves the link between ownership and consumption.
The resulting per-request accounting record should contain a timestamp, the tag set, model, provider, prompt tokens, completion tokens, and latency. That record is the unit of attribution. The reporting layer groups records by team_id, project, or another dimension and applies the relevant per-model prices to token counts. Because records are created as requests complete, totals become available continuously. Concentrate AI provides this real-time spend tracking by team, project, key, model, and provider.
Enforcing the tag schema at scale with virtual keys, RBAC, and policy
Instead of receiving a raw provider key, a team receives a gateway-issued key with immutable ownership metadata that applies regardless of application headers. Role-based access control, or RBAC, restricts key creation to authorized principals such as team leads, platform engineers, or provisioning systems. The issuance workflow requires the relevant tag fields before creating a key.
The hierarchy runs from organization to team to project to key, giving each key both ownership and budget context. Gateway policy should reject requests that lack required fields, while audit records should identify the actor, timestamp, and outcome of key creation, policy changes, and tagging violations. These controls serve different purposes within one architecture. Key metadata establishes attribution, RBAC controls who can establish it, and request policy catches noncompliance. Concentrate AI has RBAC, SSO, and audit logs as standard features with no need for an enterprise contract, so small teams can use that governance pattern.
What budget enforcement at the tag level actually looks like — and what it cannot do
With attributable spend available, the gateway can compare team or key usage against configured limits and block new requests when a threshold is reached. Early alerts give owners time to act, and anomaly detection can flag sudden spikes within a tag dimension. These are operational guardrails. Token counts for an in-flight request are known only when the provider responds, so a request admitted below a limit may complete above it. Spend limits must therefore be used as soft caps.
The more durable benefit is behavioral. A team that sees its own cost-per-task trend can identify oversized models, wasted context, and opportunities for caching instead of responding to an undifferentiated demand to spend less. Visibility makes the source of waste specific enough to address without indiscriminately reducing quality. A project-level spike can prompt investigation the same day. Threshold controls contain activity, while attribution gives engineers the context to change what generated it.
Model routing as a spend management lever, not a separate concern
Project and feature tags show what work the chosen models do. A report can therefore show which features use expensive models and what those requests cost. The practical response is to reserve frontier models for requests that need advanced reasoning and direct high-volume, low-complexity work toward cheaper or faster models. The qualitative price gap makes even partial rerouting a useful cost lever, without requiring application changes.
Reliability belongs in the same routing decision. When a primary provider is unavailable, a fallback can serve the same model or a configured equivalent, but that alternate path must remain visible in attribution. Concentrate AI provides automatic fallbacks across providers serving the same model or a configured equivalent and logs every routing decision. The accounting path can thus show where spending goes both when providers fail and when they work as usual. Teams can use the tags, records, and policy layer they already have for routing optimization, with no need for a separate observability system.
Security and compliance as a by-product of centralizing the request path
The same request boundary gives sensitive-data controls one place to run for all callers. PII and PHI redaction can run before traffic reaches a provider, without depending on each application to implement the policy separately. Concentrate AI runs PII and PHI redaction at the gateway layer and supports zero data retention, and it can enforce retention policy by provider, team, or key.
Compliance evidence still requires deliberate record design. Request records can capture actor, timestamp, model, provider, tags, and policy outcome without storing prompt or response content. Those fields support the actor, time, resource, and outcome evidence broadly expected in SOC 2 and HIPAA reviews, though neither framework mandates that specific field list. Administrative audit logs are distinct from request accounting. Concentrate AI's audit logs record administrative changes, and its HIPAA-compliant gateway offers a BAA on the paid plan. The shared enforcement boundary supports compliance work, but centralization alone is not a substitute for the required controls and agreements.
Managed versus self-hosted gateways and the operational cost of tagging
A self-hosted gateway with virtual keys, RBAC, real-time accounting, and audit records is a stateful production service. Operating it requires upgrades, high availability, database management, caching, monitoring, and on-call coverage. The model catalog also needs maintenance as providers change their APIs. That work competes directly with product engineering. A single-instance proxy also adds a point that can fail, so keeping it running reliably takes more infrastructure than the basic deployment.
A managed gateway shifts availability, upgrades, and scaling to the platform while the team configures tags, keys, routing, and budgets. Concentrate AI is fully managed, with no proxy to deploy or maintain. Its pricing includes no token markup, platform fee, card fee, or BYOK fee.
Self-hosting is a good fit for air-gapped environments, data residency requirements a managed provider cannot meet, or a platform team that already runs this infrastructure. Those requirements can justify the engineering commitment. For most AI-native teams, the practical default is a managed gateway supporting the full schema, virtual keys, RBAC, and real-time reporting. That choice lets the adoption effort concentrate on trustworthy attribution.
Rolling out the tagging architecture in a production system that already exists
The rollout should start by sending existing provider calls through the gateway without changing how the applications behave. Provider credentials move into the gateway, and the team verifies that all traffic flows through it and appears in accounting before adding tagging policy. Coverage comes before enforcement in the migration sequence. Once that path is established, team-specific virtual keys replace raw provider keys, with team_id and environment as the initial required metadata. This phase produces basic ownership visibility before the full schema is complete.
The next phase extends keys with project and feature values agreed with each team. Reports must then produce the breakdowns those teams need for budget and routing decisions. Only after the existing key inventory has migrated should policy begin rejecting requests without required tags. Reversing that order would apply the new contract before existing callers were ready to satisfy it.
Budget limits and routing optimization follow once attribution data is accumulating. Teams can set spend thresholds, configure alerts, and identify the first low-complexity features suited to cheaper models. Each phase depends on evidence from the previous one. The approach can deliver basic team-level attribution within days of the first deployment, without waiting for every control to be complete. By the time the next provider invoice arrives, its total has an existing request-level explanation by owner and workflow rather than becoming the starting point for reconstruction.