AI Security Risk Management for Non-Engineering Stakeholders
Finance and security leaders need these infrastructure controls to govern AI risk.
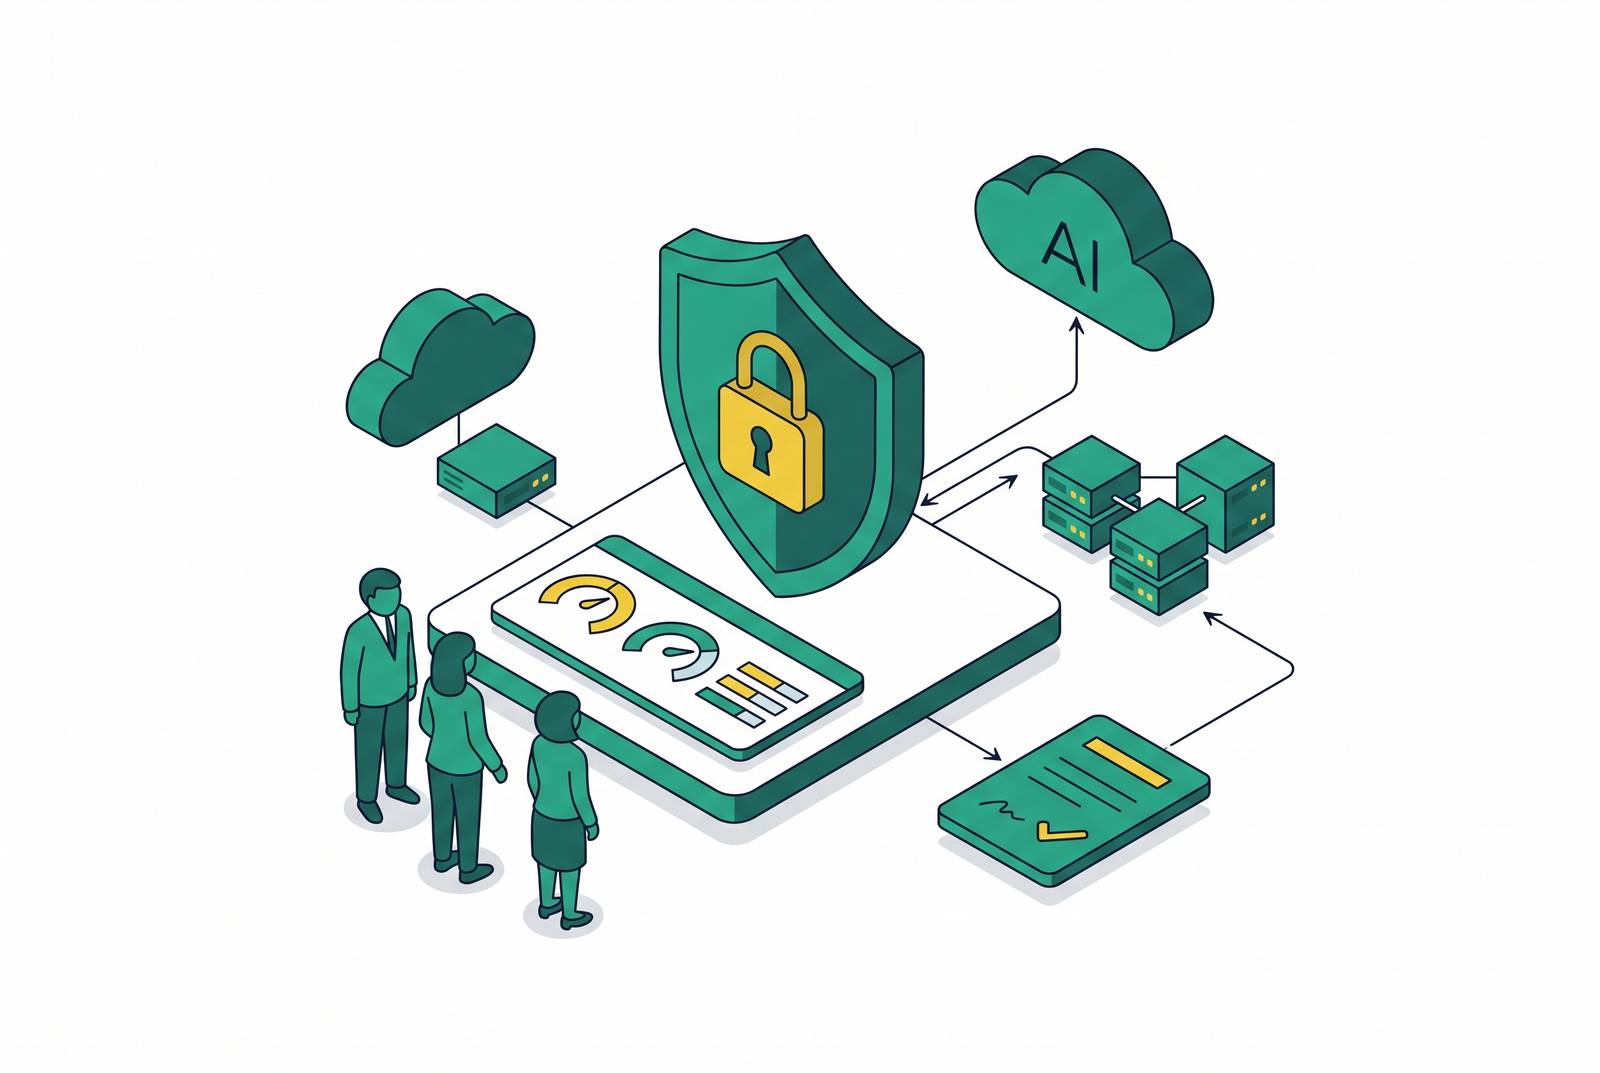
AI risk has moved out of engineering and onto the desks of finance and security leaders. The reason is simple: production AI now spends money at nonlinear rates, sends customer data to third parties, and fails in ways that hit revenue. This article gives non-engineering stakeholders the four controls and the four questions they need to govern that risk.
Why AI security risk now lands on finance and security desks, not just engineering ones
A CFO asks what the company spent on AI last month and nobody can answer without pulling logs. Legal asks whether customer data went to a model provider, and nobody can say. These are not hypothetical moments. They are the new default in companies that moved AI from experiments into production without moving governance along with it.
The shift matters because production AI carries a different weight than experimental AI. An experiment that leaks data costs a team a postmortem. A production system that leaks data costs the company a regulatory event. The people who own regulatory events, budgets, and contractual obligations are not engineers. They are finance and security leaders. Token-based billing scales nonlinearly and compounds in agentic workflows. A single user action can trigger many model calls, and a year of budget can burn in months. Finance teams have no prior playbook for this pattern because it is structurally unlike seat licensing.
Sensitive customer data now sits inside prompts headed to external providers. PII, PHI, and financial records cross an organizational boundary with every AI call. So each call can be a regulated-data disclosure event, and security and compliance teams own those events. Provider outages interrupt customer-facing products now, not just internal tools. Reliability has landed on the operational risk register shared by the CISO, the CFO, and engineering.
The controls that manage these risks exist. Spend attribution, data redaction, access governance, and fallback routing are built into the infrastructure layer of well-run AI systems. They work only when non-engineering stakeholders know what to ask for and what to require. That is the gap this piece closes.
What an AI gateway is and why it is the right place to look for controls
An LLM gateway is the infrastructure layer between applications and model providers. Authentication, routing, spend enforcement, data policy, and logging are decided once there, for all AI traffic, rather than rebuilt in every application. Think of it as the corporate card program for AI calls. One place where limits, visibility, and rules apply regardless of who is spending.
Without a gateway, each team stores its own provider keys, writes its own retry logic, tracks spend in its own format, and applies or skips its own data handling rules. That fragmented surface is exactly what finance and security cannot govern. The virtual key mechanism is the concept that matters for non-engineers. The gateway holds the real provider API keys. Applications get virtual keys scoped to a team, project, or use case. It enforces spend limits, data policy, and access rules on every call made with those keys.
Here is the operational point. Policy is enforced outside the LLM and outside application code. A developer who forgets to add a check does not create a gap. An agent that takes an unexpected path does not bypass the policy. The gateway catches it regardless.
The threshold for needing a gateway is usually when a team runs more than one AI-integrated service, or when meaningful production spend begins. The signal is when the CFO's question about monthly AI cost requires investigation rather than a dashboard lookup. Managed gateways are now available as fully hosted services, with no proxy to deploy or maintain. The governance layer does not require a platform engineering team to stand up. Bifrost, for example, is a high-performance enterprise AI gateway that unifies access to 23-plus providers and 10,000-plus models through a single OpenAI-compatible API. Concentrate AI operates similarly as a fully managed gateway: one API across models from dozens of providers, with spend limits, data redaction, audit logs, and SSO built in, and no markup or platform fees. The Pareto frontier point is worth knowing too. Of 20 frontier models tracked across OpenRouter in Q2 2026, only six sit on the Pareto frontier across cost, quality, and speed at once.
Spend visibility: what finance leaders need to require before approving AI budgets
Token-based AI spend is ungovernable without real-time, granular attribution. The absence of that attribution is itself a financial risk, not just an operational inconvenience. Tokens are not like seats. They scale nonlinearly, multiply geometrically in agentic workflows, and are volatile and difficult to forecast. A 2026 analysis found a price spread of over 48x between the cheapest and most expensive frontier models for equivalent sessions. Finance teams need a new mental model, not a mapped version of the SaaS seat model.
The structural governance that works is a three-layer hierarchy. An org-wide ceiling sits at the top. Team and project allocations that reflect actual business priorities come next. Individual or per-key caps sit at the bottom. When teams know their allocation, they make different decisions about which tasks are worth AI spend. Granular spend attribution, by team, project, key, model, and provider, is the foundation of AI budget governance. Without it, finance teams cannot tell efficient model selection from runaway consumption. An AI gateway should make this visibility real-time and queryable, not reconstructed from invoices, so finance and engineering can course-correct before a forecasting miss becomes a budget overrun.
The meaningful spend metric is not cost per token. That metric rewards using AI less. The right metric is cost per task, per workflow, or per resolved unit of work, compared against the cost and time of the process AI replaced. Finance leaders should require this framing in any AI ROI reporting. Token-based billing carries financial and operational risks that existing playbooks do not cover. The controls that mitigate them live in the infrastructure layer. Concentrate AI centralizes real-time spend tracking by team, project, key, model, and provider, so finance leaders can see allocation against actual consumption without reconstructing costs from invoices or waiting for month-end billing.
Data redaction and zero data retention: what security leaders need to know before customer data touches a model
The core question this section answers: how do you prevent sensitive customer data from being sent to OpenAI or other LLM APIs? The answer is to enforce PII and PHI redaction at the gateway layer, before any data leaves your network, and to pair that with zero data retention agreements where compliance requires them. This is not developer discipline. It is deterministic policy enforcement.
Every prompt sent to an external model provider is a data transfer to a third party. Without active redaction at the gateway layer, regulated data reaches those providers by default. Model providers retain API data by default for periods that vary by provider and plan. OpenAI retains API data for 30 days for abuse monitoring by default. Zero data retention exists, but it is typically a negotiated enterprise agreement, not the default on pay-as-you-go accounts. Security teams need to verify this per provider, not assume it.
The architectural fix is PII and PHI redaction running at the gateway before any data leaves the organization's control. A developer who forgets the check does not create a gap because the gateway catches it regardless. ZDR for AI is a technical and contractual guarantee that prompts, context windows, and outputs are processed in memory only and never written to persistent storage. No logs, no training datasets, no databases. When the session ends, the data is gone. HIPAA does not require zero data retention for workflows handling PHI. In fact, HIPAA mandates retaining PHI-related documentation for at least six years.
Audit capability does not require storing content. Timestamps, token counts, policy outcomes, and anomaly flags satisfy compliance requirements. Security teams should not accept "we need to store prompts to audit them" as a reason to skip ZDR. Before any AI workflow goes to production, security leaders need answers to four questions. Does redaction run before data leaves our network? Which providers have signed a BAA? Does our fallback routing respect the same data policy as the primary route? Can we produce a per-request audit trail without retaining prompt content?
Access governance: how RBAC and audit logs give security teams visibility without slowing engineering
AI access governance should follow the same logic as physical access controls. The right people can call the right models with the right data, and every access event is logged in a way that supports review and audit. RBAC for AI maps to questions security teams already own. Who can call which models? Which virtual keys map to which applications? What data can be sent through each key? Does PII redaction or ZDR apply to a given key? Does a request log and audit log exist for review?
Workspaces and scoped keys let a customer-facing application have stricter access than an internal evaluation project. The same model can be available to both teams under different policies, enforced at the gateway rather than by trusting each team to self-govern. Done at the gateway layer, RBAC removes engineering work. Developers do not write access logic into applications. The gateway enforces it.
SSO and SCIM integration matters at scale. When someone leaves or a new team forms, access should sync automatically from the identity provider, so you do not need manual key revocation. Manual revocation is the identity provisioning friction point that creates audit gaps at growing organizations. Audit logs that capture who called what, when, under which policy, with what outcome, without storing prompt content, give security teams the reviewable record they need without creating a secondary data liability.
The forward-looking compliance requirement is that policy is enforced outside the LLM, deterministically, at the infrastructure layer. Not inside the model. Not left to developer judgment. Buyers and auditors are increasingly requiring this as a condition of approval.
Fallback reliability: why provider outages are a compliance and financial risk, not just an engineering problem
Provider outages are routine. In a correlated infrastructure environment, they can affect multiple providers simultaneously. Automatic, policy-aware fallback routing is a risk management requirement, not a nice-to-have. Major AI providers publish uptime figures, but their SLAs vary significantly by tier. Enterprise-tier SLAs exist but are not the default for teams on standard or pay-as-you-go plans. Security and procurement teams should verify which SLA tier applies to their actual contract.
A tiered fallback chain with circuit breakers is the operational standard. Without a circuit breaker, fallback logic can spend 5 seconds timing out against a failed provider before it routes to another, for every single request throughout an outage. Circuit breakers stop retrying a failed provider immediately, so you do not time out on every request. Without them, the fallback itself becomes a latency problem.
The compliance caveat is what security leaders must enforce. A fallback route must respect the same data policy as the primary route. Failing over from a HIPAA-compliant, BAA-covered provider to an uncovered one to stay online is not an acceptable trade. Policy-aware fallback routing is a compliance requirement, not an engineering preference. The financial dimension is equally direct. An unmanaged outage that takes a customer-facing AI product offline is a revenue event. A fallback that silently routes to an uncovered provider is a compliance event. Both are costs that finance and security own. A managed gateway handles the fallback chain without application code changes, which is the practical payoff for teams that do not want to build and maintain this logic themselves.
The four questions finance and security leaders should ask before any AI system goes to production
The four controls translate directly into four questions. Finance and security leaders should be able to answer all four before signing off on any production AI deployment. On spend: Can we see, in real time, what each team, project, key, model, and provider is spending, and can we set allocation limits that enforce before the invoice arrives? On data: Does redaction of PII and PHI run at a single chokepoint before data leaves our network, is zero data retention in place where required by HIPAA or contract, and has our provider signed a BAA? On access: Do we have RBAC and scoped keys that enforce different data policies for different applications, SSO provisioning that syncs with our identity provider, and audit logs that support compliance review without storing prompt content? On reliability: Is there an automatic fallback chain with circuit breakers, do all fallback routes respect the same compliance policy as the primary route, and does failover happen without application code changes?
A managed gateway that satisfies all four is the structural answer. It moves provider complexity, compliance enforcement, and spend attribution into the infrastructure layer and out of application code and developer discipline. Knowing these four questions does not require reading the code. It requires knowing that the controls exist, where they are enforced, and that the infrastructure team can demonstrate them. That is the governance role finance and security already play for every other system. AI is not an exception.