Attributing AI Infrastructure Costs to Business Units and Products
Organizations need infrastructure-level cost tracking to attribute AI spending to the right teams.
Attributing AI Infrastructure Costs to Business Units and Products.
AI cost attribution as a production engineering problem
Zylo's SaaS Management Index shows enterprise LLM spending has surged past $8.4 billion, with AI-native application spend rising an average of 108% year over year and 393% inside large enterprises alone Zylo's 2026 SaaS Management Index. That's the kind of number that shows up in board meetings, and when spend gets that large, misattributing it hits the P&L directly rather than remaining a mere accounting inconvenience Zylo's 2026 SaaS Management Index.
Awareness of the problem has exploded, but control hasn't caught up. The State of FinOps 2026 report found that 98% of organizations now list AI cost management as a priority, up from just 63% the year before. Nearly everyone is worried. Almost nobody has fixed it. That gap, between concern and actual operational control, is the defining challenge facing platform teams and finance departments right now.
SpendHound's 2026 AI Spend Report, based on responses from 172 finance and procurement leaders, found that 46% of organizations exceeded their AI budgets in 2025. Close to half either hadn't seen measurable return on that spend or said it was too early to tell SpendHound's 2026 AI Spend Report. Deloitte's enterprise AI report found that worker access to sanctioned AI tools grew 50% in 2025, meaning cost is spreading through the organization faster than any governance process can track it.
Agentic workloads make the surface area worse. Gartner predicts that 40% of enterprise applications will be integrated with task-specific AI agents by the end of 2026, up from under 5% in 2025. Each agent doesn't make one call, it makes several, chained across planning, tool use, and validation. Multiply that by every product team running agents, and the number of billable events an organization needs to track explodes.
Then there's the spend nobody sees at all. Roughly two-thirds of employees have accessed GenAI assistants through personal accounts, and more than half have entered confidential information into public AI tools. None of that appears on an infrastructure invoice, because it never touched the infrastructure to begin with.
A structural mismatch underlies this. The teams generating AI spend, product, marketing, data science, are rarely the teams holding the invoice, which usually lands on platform, DevOps, or finance. Fixing that requires a tagging and allocation strategy built into the infrastructure itself, not reconstructed after the fact from a monthly bill.
The gap between AI infrastructure costs and what provider invoices cover
Token spend, the input and output tokens billed by a model provider, is the line item everyone sees first. It's also just the tip of the stack.
None of that appears on any LLM provider invoice. Then there's data retrieval and storage, vector search, embedding generation, object storage reads that feed retrieval-augmented generation pipelines. Networking adds another layer entirely, egress charges, cross-region calls, VPC traffic. Mavvrik and Benchmarkit's 2025 State of AI Cost Governance report found network access was the second-largest source of unexpected AI spend, at 52%, trailing only data platform costs at 56%.
Orchestration overhead piles on top of that, retries, tool invocations, agent planning steps, all billed separately from whatever the model itself returns. And developer tooling, shared coding assistants used across multiple teams, adds shared cost that doesn't cleanly belong to any one budget.
Agentic workflows compound the arithmetic. A single user request can trigger model calls across planning, tool use, validation, and final response generation, and any budget built on single-call economics breaks the first time an agent runs a multi-step task. The blunt truth: an OpenAI or Bedrock invoice tells an organization total spend by API key, nothing more. It doesn't say which team, product, or feature drove that spend. Attribution has to be built upstream of the invoice. Trying to reverse-engineer it afterward is a losing game. Hybrid infrastructure makes this harder: 61% of companies already run hybrid AI infrastructure, yet only 35% include on-prem AI costs in reporting, per the same Mavvrik/Benchmarkit report (a structural blind spot).
The difference between showback and chargeback depends on sequence
Showback and chargeback get used interchangeably in casual conversation, but they solve different problems, and the order in which an organization deploys them affects how quickly cost accountability takes hold and how much rework is needed later.
Showback shows teams what they consumed and what it cost, without moving any money. Nobody gets billed. It's low-friction politically, which makes it the right starting point while an organization is still building basic cost awareness across teams that have never had to think about token pricing before.
Chargeback goes further: consumed costs get allocated directly to the consuming business unit's P&L. When marketing runs an LLM-powered campaign, the token costs land on marketing's budget, not IT's. That's the point where cost ownership becomes real, and also where disputes start if the groundwork hasn't been laid.
The recommended sequence is to run showback for 60 to 90 days before flipping the switch to chargeback. That window gives teams time to actually understand what's driving their costs before budget responsibility shifts onto them. Skip that step, and the result is predictable: disputes over disputed line items, and teams gaming their usage reports to avoid getting hit with charges they don't understand.
Before either model can work, a few organizational questions need answers. Who owns the cost attribution policy: platform engineering, FinOps, or finance? What happens when a team blows past its allocation, and who has the authority to act on it? And for shared services, a centrally managed embedding pipeline feeding three different products, is the cost split proportionally, split by measured usage, or excluded from chargeback altogether?
None of this works, showback or chargeback, without instrumentation. A chargeback report generated at month's end tells a finance team what already happened. Enforcement has to happen at the moment a request is made to stop a department from blowing through its allocation mid-month. Most organizations get enforcement timing wrong, and that's exactly the gap the next section addresses.
Building the event schema that makes attribution work
If every application team logs its own field names, in its own format, finance ends up holding a pile of records that can't be joined together. Attribution confidence collapses the moment that happens. A shared, enforced event schema isn't a nice-to-have. It's the prerequisite for any allocation model to function at all.
A workable per-request schema needs a specific set of fields. Provider, identifying OpenAI, Anthropic, Bedrock, Vertex AI, or whichever service handled the call. The exact model identifier, not just the provider name, since cost varies wildly between model versions from the same vendor. Input tokens, output tokens, and cached input tokens, granular enough to support true per-token pricing math.
A billing_rule_version field lets an organization restate historical costs correctly when a provider changes pricing mid-month, mapping unit price × tokens to a USD cost per request. Without it, cost reports from before and after a pricing change simply won't reconcile.
The math itself is simple: unit price multiplied by tokens equals the dollar cost of that request. The complexity isn't in the formula, it's in making sure every single request logs the fields needed to run it.
Naming conventions need enforcement, not a style guide that teams are free to ignore. Application teams that drift into incompatible tags produce records nobody downstream can join, and that drift happens quietly, one deploy at a time, until someone tries to run a report and finds half the data unusable.
Where that enforcement lives matters a great deal. Gateway-level tagging holds up far better than asking every application developer to instrument every call by hand, because the gateway intercepts every request regardless of which SDK or programming language the application happens to use.
Agentic workloads need one more thing from the schema: a task-level or session-level grouping field. A single agent run can generate dozens of individual events, all tied to the same underlying task. Without a shared session ID linking them, there's no way to answer a simple question like "what did this one agent run actually cost," which defeats a large part of the reason for building the schema in the first place. Per-million unit prices and computed cost in USD are calculated at log time using the rate in effect, not reconstructed later.
Tagging enforcement at the LLM gateway: the attribution control plane
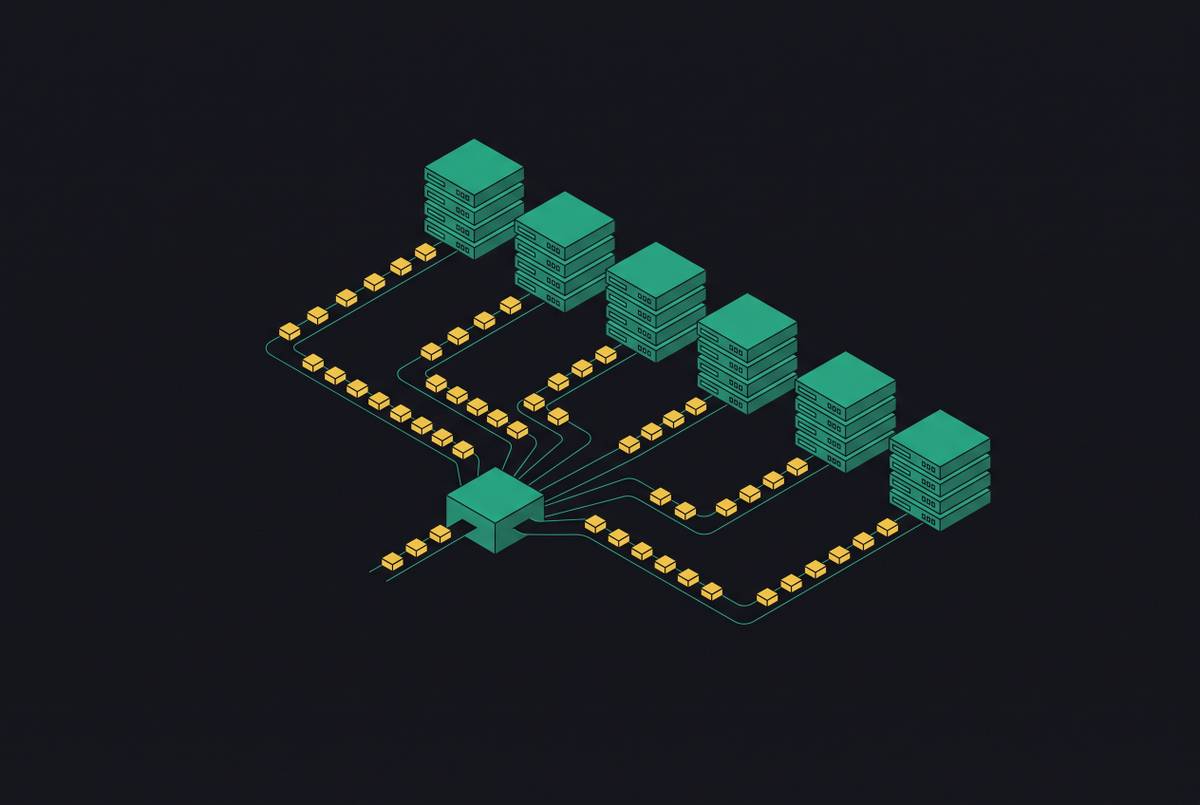
An LLM gateway sits between applications and model providers as a single control layer, exposing one API for routing, authentication, failover, caching, cost attribution, and policy enforcement across every model call an organization makes. Instead of each application team wiring up its own SDK integration per provider, everything routes through one endpoint.
Application-level tagging fails at scale for reasons that are almost mechanical. Different teams reach for different SDKs, different languages, different naming conventions, and drift is simply inevitable once enough teams are involved. Teams under deadline pressure skip instrumentation entirely when it's optional, because shipping the feature always wins over tagging the API call correctly. And every time a provider ships a new model or a new pricing tier, that change needs to propagate into every application separately, rather than into one shared place.
A gateway flips that arrangement. Attribution headers become mandatory at request time: a request missing a team_id, or carrying an unrecognized service identifier, gets rejected or quarantined before it ever reaches the provider. Virtual keys bundle access permissions, per-team budgets, and rate limits into a single credential, so each team operates against a key scoped to its own allocation rather than a shared organizational key that obscures who's spending what. Telemetry gets emitted for every request, regardless of which application or model issued it, which means the attribution record is never simply missing.
That's also the distinction between a gateway and a plain proxy. A proxy forwards requests. A gateway becomes the system of record for which team called which model, at what cost, under which policy, and that record is what makes chargeback defensible instead of disputed.
Teams weighing how to actually implement this face a build-versus-buy decision. Managed gateway services take the operational burden of running gateway infrastructure off engineering teams' plates entirely, which matters most for fast-growing organizations where AI usage is expanding faster than internal governance can keep pace. A managed, unified API covering a broad range of providers with real-time spend dashboards is the practical alternative to maintaining separate provider keys and bespoke integration code for each one. Self-hosted, open-source options like LiteLLM remain popular in Python ecosystems for teams that want to control their own infrastructure, though they introduce runtime overhead and operational maintenance. The right call depends heavily on how much bandwidth the platform team actually has to spare. Multi-provider context makes gateway enforcement essential: 37% of enterprise CIOs ran five or more models in production in 2025, up from 29% a year earlier, per an a16z survey (attribution logic written against a single provider breaks as soon as the second provider is added).
Routing strategy as a cost lever: how model selection affects the attribution baseline
Attribution data that just sits in a dashboard isn't worth much. The first real decision it should inform is which model handles which workload.
Not every task needs a frontier model. Code completion, simple Q&A, basic formatting, these are routine enough to hand off to smaller, cheaper models without any noticeable quality loss. Ramp's AI token spend management tool found that roughly a third of businesses using it found opportunities to shift work off frontier models onto more efficient alternatives. That's not a marginal optimization; it's a third of workloads potentially running at a fraction of the cost.
A gateway typically supports several routing strategies simultaneously. Cost-based routing sends lower-complexity requests to cheaper models automatically, based on how the request gets classified. Latency-based routing sends traffic to whichever provider is responding fastest, which matters for latency-sensitive features like live chat. Quality- or task-based routing matches model capability to task complexity at the individual request level, rather than applying one model choice across an entire feature. Automatic failover routing detects when a primary provider goes down and switches to the next option in a fallback chain, without the application needing its own retry logic. And provider uptime-based routing watches for a provider's uptime dropping below a set threshold, say 90%, and reroutes to the best available alternative automatically.
Attribution makes all of this auditable rather than theoretical. When a team switches a workload from a frontier model down to something smaller, the cost delta appears immediately in that team's dashboard. The savings are visible and attributable, not buried somewhere in an aggregate invoice line.
Agentic workloads raise the stakes here considerably. Each agent task fires off multiple model calls, and overhead stacks up across planning, tool use, and validation steps. Cost-based routing applied to individual calls has an outsized effect once a single user action can trigger an entire chain of downstream requests.
A widely cited 2025 benchmark comparing gateway performance at high request volume was authored by one of the gateway vendors itself, using a mocked LLM backend rather than a real one. Those numbers measure raw gateway overhead in a lab setting, not how the gateway behaves in production against actual provider latency. Anyone citing vendor-published benchmark figures should treat that gap seriously.
Budget thresholds, anomaly detection, and real-time enforcement
Visibility on its own doesn't stop overspend. A chargeback report tells an organization what happened last month. Real-time alerting on token consumption is what actually prevents this month from turning into next month's bad report.
The minimum viable version of this looks like three things working together: real-time alerts on token consumption broken out by team and use case, hard budget thresholds enforced at the gateway that block requests once a team's allocation runs out (not soft alerts that just notify someone after the damage is done), and automated anomaly detection that flags spend spikes before they become a pattern.
A practical starting rule looks like this: flag any business unit where variance exceeds 3% or $500, whichever number is larger. For a team billed at $18,000 a month, that works out to a tolerance of $540 before an alert fires. Simple, but it catches the drift before it compounds.
Agentic workloads need circuit breakers specifically, because a single misconfigured agent can burn through an entire month's token budget in a matter of hours. Without task-level spend limits or a hard circuit breaker, there's no mechanism to stop a runaway agentic loop before it turns into a real cost overrun.
Budget controls also need to work hierarchically: enforceable at the organization level, the team level, the project level, and down to the individual API key. That way, one team's overrun doesn't take down access for the entire organization, and one misbehaving application inside a team doesn't quietly exhaust that whole team's quota.
Getting to "real-time" isn't just a dashboard refresh setting, it's a technical requirement. Cost has to be computed and recorded the moment a request happens, not during invoice reconciliation weeks later. That means the computed USD field and the billing_rule_version field from the event schema aren't optional extras, they're prerequisites for enforcement to work at all. Everything here loops back to the instrumentation built earlier in the pipeline.
One operational detail organizations tend to skip: a runbook for what happens the moment a hard limit actually fires. Who gets paged. Who holds override authority. How limits get adjusted mid-period without turning every threshold into a fire drill. Without that runbook, the first real budget breach becomes a scramble instead of a known procedure.
Allocating shared infrastructure and agentic workloads
Not every cost maps cleanly to one team, and shared infrastructure is where attribution models tend to get tested hardest.
Direct attribution works when costs map one-to-one to the team making the request, a dedicated fine-tuned model serving one product, for instance. It breaks down fast for shared embedding pipelines or a centrally managed retrieval layer feeding multiple products at once, since there's no single requesting team to point to.
Proportional allocation handles that case by splitting shared costs according to each team's share of total request volume or token consumption over a given period. It's fairer than a flat split when usage is genuinely uneven, though it requires the same instrumentation discipline as everything else in this pipeline, since proportional splits are only as accurate as the underlying request logs feeding them.
Fixed allocation takes a simpler route: shared costs get distributed by a pre-negotiated percentage, agreed on ahead of time rather than recalculated from usage data every period. It's less precise, but it's predictable, and predictability has its own value when finance teams are trying to build annual budgets around numbers that don't move every month.
Agentic workloads sit somewhere at the intersection of all three problems this piece has covered: multiple calls per task, shared infrastructure underneath them, and real-time enforcement that has to catch runaway spend before it compounds. Getting attribution right here isn't a finance exercise bolted on after the fact. It's a production engineering decision, built into the gateway and the event schema from day one, or it doesn't hold up once agents start running at scale.
Sources
- Chargeback vs. Showback: FinOps Cost Allocation Guide 2026
- AI Cost Attribution: LLM Chargeback by Business Unit - DEV Community
- How Much Does AI Cost in 2026? Pricing & Budgets | Zylo
- AI Infrastructure Cost Allocation: What You're Actually Paying
- 2026 AI Cost Governance Report: Visibility & Forecasting
- AI Infrastructure Costs: Why They're Hard to Measure
- Chargeback Vs. Showback: Cloud Cost Allocation Models Explained (2026)
- IT Chargeback for AI Spend: How to Turn Runaway AI Costs Into Accountability - brightfin