Intelligent LLM Routing Based on Cost, Speed, and Quality
Balances cost, speed, and quality as simultaneous signals rather than competing priorities.
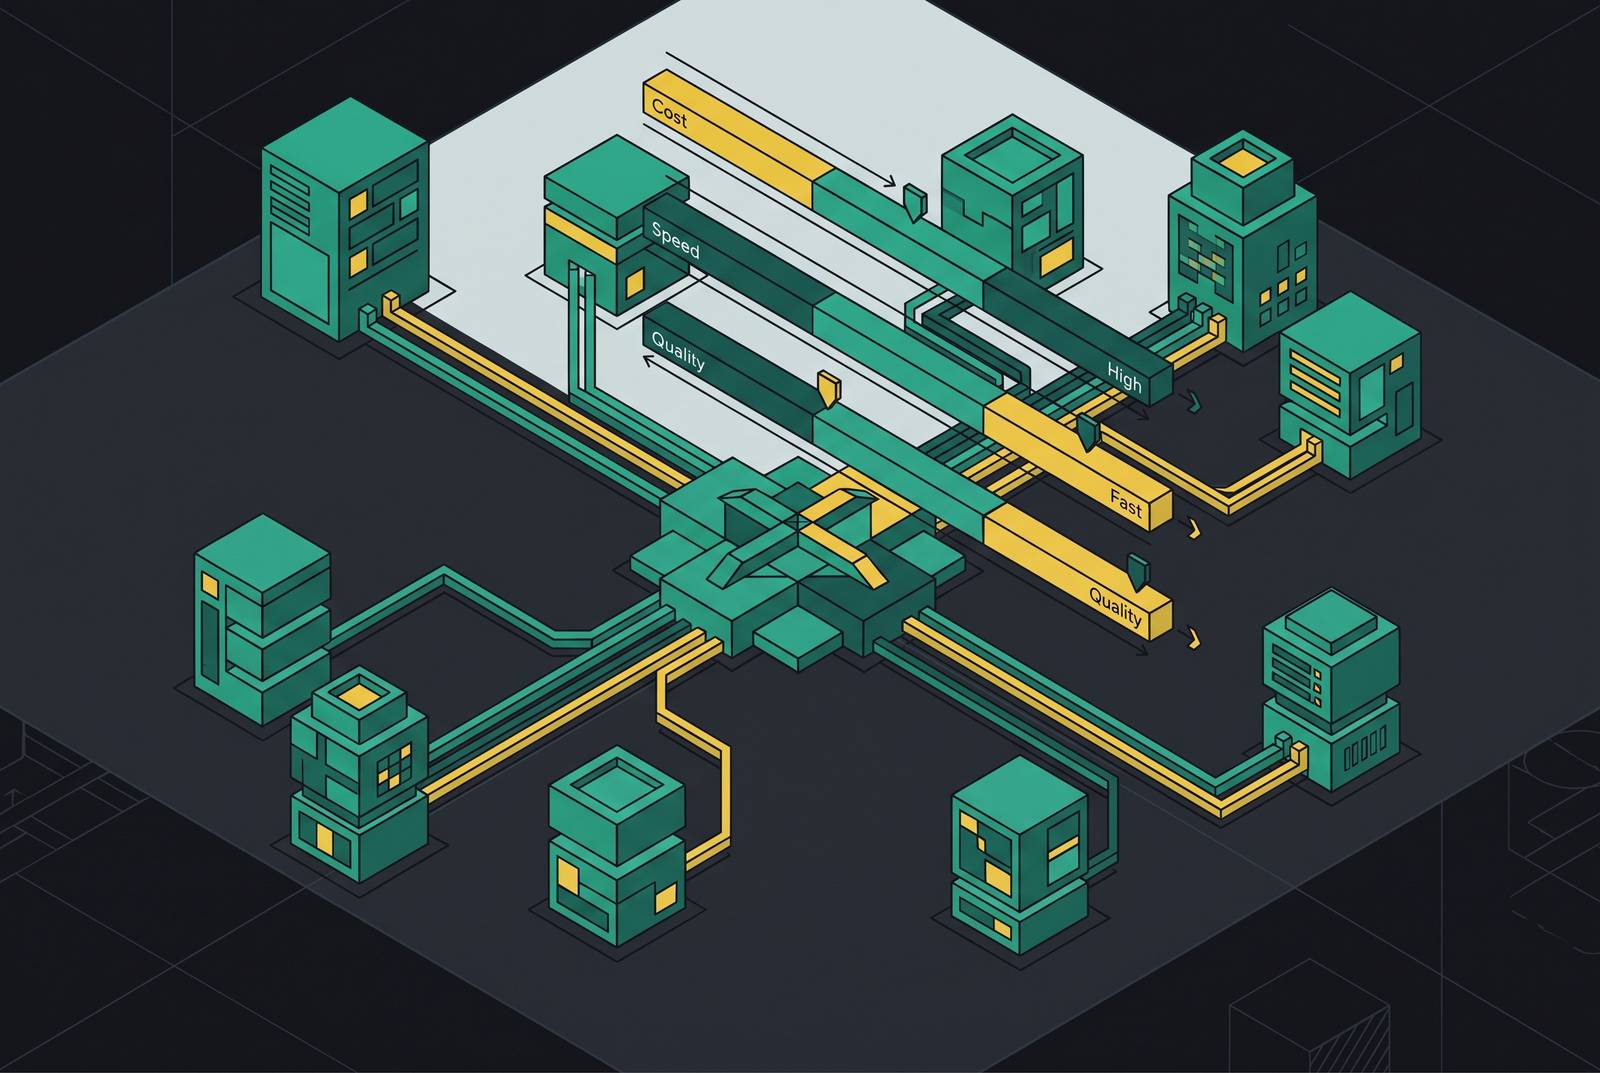
Intelligent LLM routing works when cost, speed, and quality are treated as three signals that fire at the same time, rather than a priority order where quality wins and the other two fight for scraps. This piece covers what that looks like in production: the control layer that makes routing possible, the per-workload math behind it, the three tiers of implementation teams actually build, and the fallback and spend-visibility work that keeps the whole system honest.
Why production AI teams need a routing layer
The pattern appears the same way almost everywhere. One team gets an API key, wires it into their service, and ships. A second team does the same thing a few weeks later, with a different provider or a different key. Months pass, and nobody in the organization can answer a simple question: who is calling which model, at what cost, with what data. That gap doesn't come from carelessness. It comes from the absence of a layer whose job is to know the answer.
Without that layer, every new provider adds its own SDK, its own credentials, and its own blind spot. Credentials get hardcoded. Observability stays local to whichever team built the integration, so nobody else can see it. Guardrails, if they exist at all, live in one service and nowhere else. Each additional model a team wants to use adds complexity directly into application code. The cost of adopting a new model keeps rising instead of staying flat.
A gateway fixes the structural problem by sitting as a reverse proxy between the application and every provider. The application sends every request to a single OpenAI-compatible endpoint, regardless of which model ends up handling it. On the way through, the gateway authenticates the caller, resolves which tenant is making the request, checks policy, routes to a model, meters the tokens used, enforces budget limits, and logs the whole transaction. None of that logic has to live in application code anymore, and none of it has to be rebuilt every time a new provider gets added.
Skip that layer and the failures that follow are predictable: API keys sitting unmonitored in source repositories, spend that runs ahead of anyone's awareness across different teams, and no forensic trail to pull when a security audit asks who touched what. A routing layer is the control plane that every other decision in this piece depends on, because none of the cost, speed, or quality tradeoffs that follow can be enforced without somewhere to enforce them.
Cost, Speed, and Quality as Simultaneous Signals
Having a gateway in place solves the visibility and control problem. It doesn't solve the harder problem that sits beneath it: what the gateway should actually do with a given request. Most teams, even ones with a gateway already running, default to a version of "send it to the best model unless cost forces us down a tier." That rule sounds conservative and reasonable. In practice, it's a proxy for "send everything to the default model," and it throws away most of the optimization value the gateway was built to capture.
No single workload has the same requirements as the next one. Summarizing an email thread has a different quality bar, latency tolerance, and acceptable cost than generating a multi-step code change, and both are different again from a customer-facing chat interaction happening in real time. It's a forfeit of the decision entirely, made once, by default, and then never revisited.
A common objection is that quality should always come first, because quality is non-negotiable. Quality isn't a property of a model, it's a property of a task, which is what that objection gets wrong. A lighter model correctly answering a simple classification question delivers higher quality per dollar spent than a frontier model answering the same question at 30 times the cost, so sending that task to the frontier model spends budget on a capability it never needed.
Cost, speed, and quality have to be live at the same time, each expressed as its own measurable target, because a routing policy that ranks them in order will always collapse back into the same default. The alternative is treating the three signals as a policy, written down, specific to each workload, and enforced by the gateway rather than assumed by whichever engineer wired up the first integration.
Defining and weighting the three signals for a workload
Before any of the three signals can be weighted against each other, each one needs its own concrete definition, tied to the workload it's governing.
Cost is the easiest signal to get wrong, because the obvious unit, cost per token, actually rewards using AI less rather than using it well. A team trying to minimize cost per token will just send fewer tokens, not better-routed ones. The units that matter are cost per task, cost per workflow, or cost per resolved unit of work. For a customer support chatbot, that means cost per resolved ticket, not cost per message exchanged. A tiered architecture that routes simpler queries to cheaper models produces a median blended cost far below sending every ticket to a frontier model, and the gap between those two approaches is decisive at scale. Cost also has to account for the infrastructure path a request takes, beyond the provider's list price. Routing a Claude Haiku request through an aggregator shows roughly 780ms at the median versus roughly 620ms calling Anthropic directly, so the aggregator layer itself adds latency on top of whatever the token price looks like. A cost signal that only looks at per-token pricing misses that overhead.
Speed needs a different metric depending on what the workload actually is. Time-to-first-token matters for anything streaming, interactive, or agentic, where a user or a downstream system is waiting on the first piece of output before anything else can happen. Total response time matters more for batch jobs or background processing, where nobody's watching a cursor blink. The distinction matters most in agent workflows, where a single user action can trigger a chain of sequential LLM calls. A 200ms provider advantage becomes a multi-second difference in how fast the agent finishes its task.
Quality has to be operationalized per task rather than treated as a single capability score: a benchmark result on an evaluation set relevant to the task, a human preference rate measured in A/B testing, or a task-success rate measured against real production examples. For document classification, that might be a labeled accuracy benchmark. For customer support chat, it might be a human-rated resolution quality score. For code generation, it might be a pass rate on a held-out suite of real tickets. LMSYS's RouteLLM benchmarks show that a learned router can reach 95% of GPT-4's quality while running at a fraction of GPT-4's cost, which makes a specific point about how quality thresholds should be written. The policy doesn't need to express the quality maximum. It needs to express the quality threshold, the minimum bar a response has to clear for a given task. That threshold works best as a pass/fail gate, "must score above X on task Y," rather than as something the router tries to continuously maximize. A router chasing maximum quality on every request will quietly route everything back to the most expensive model available, which defeats the entire exercise.
Three tiers of routing implementation
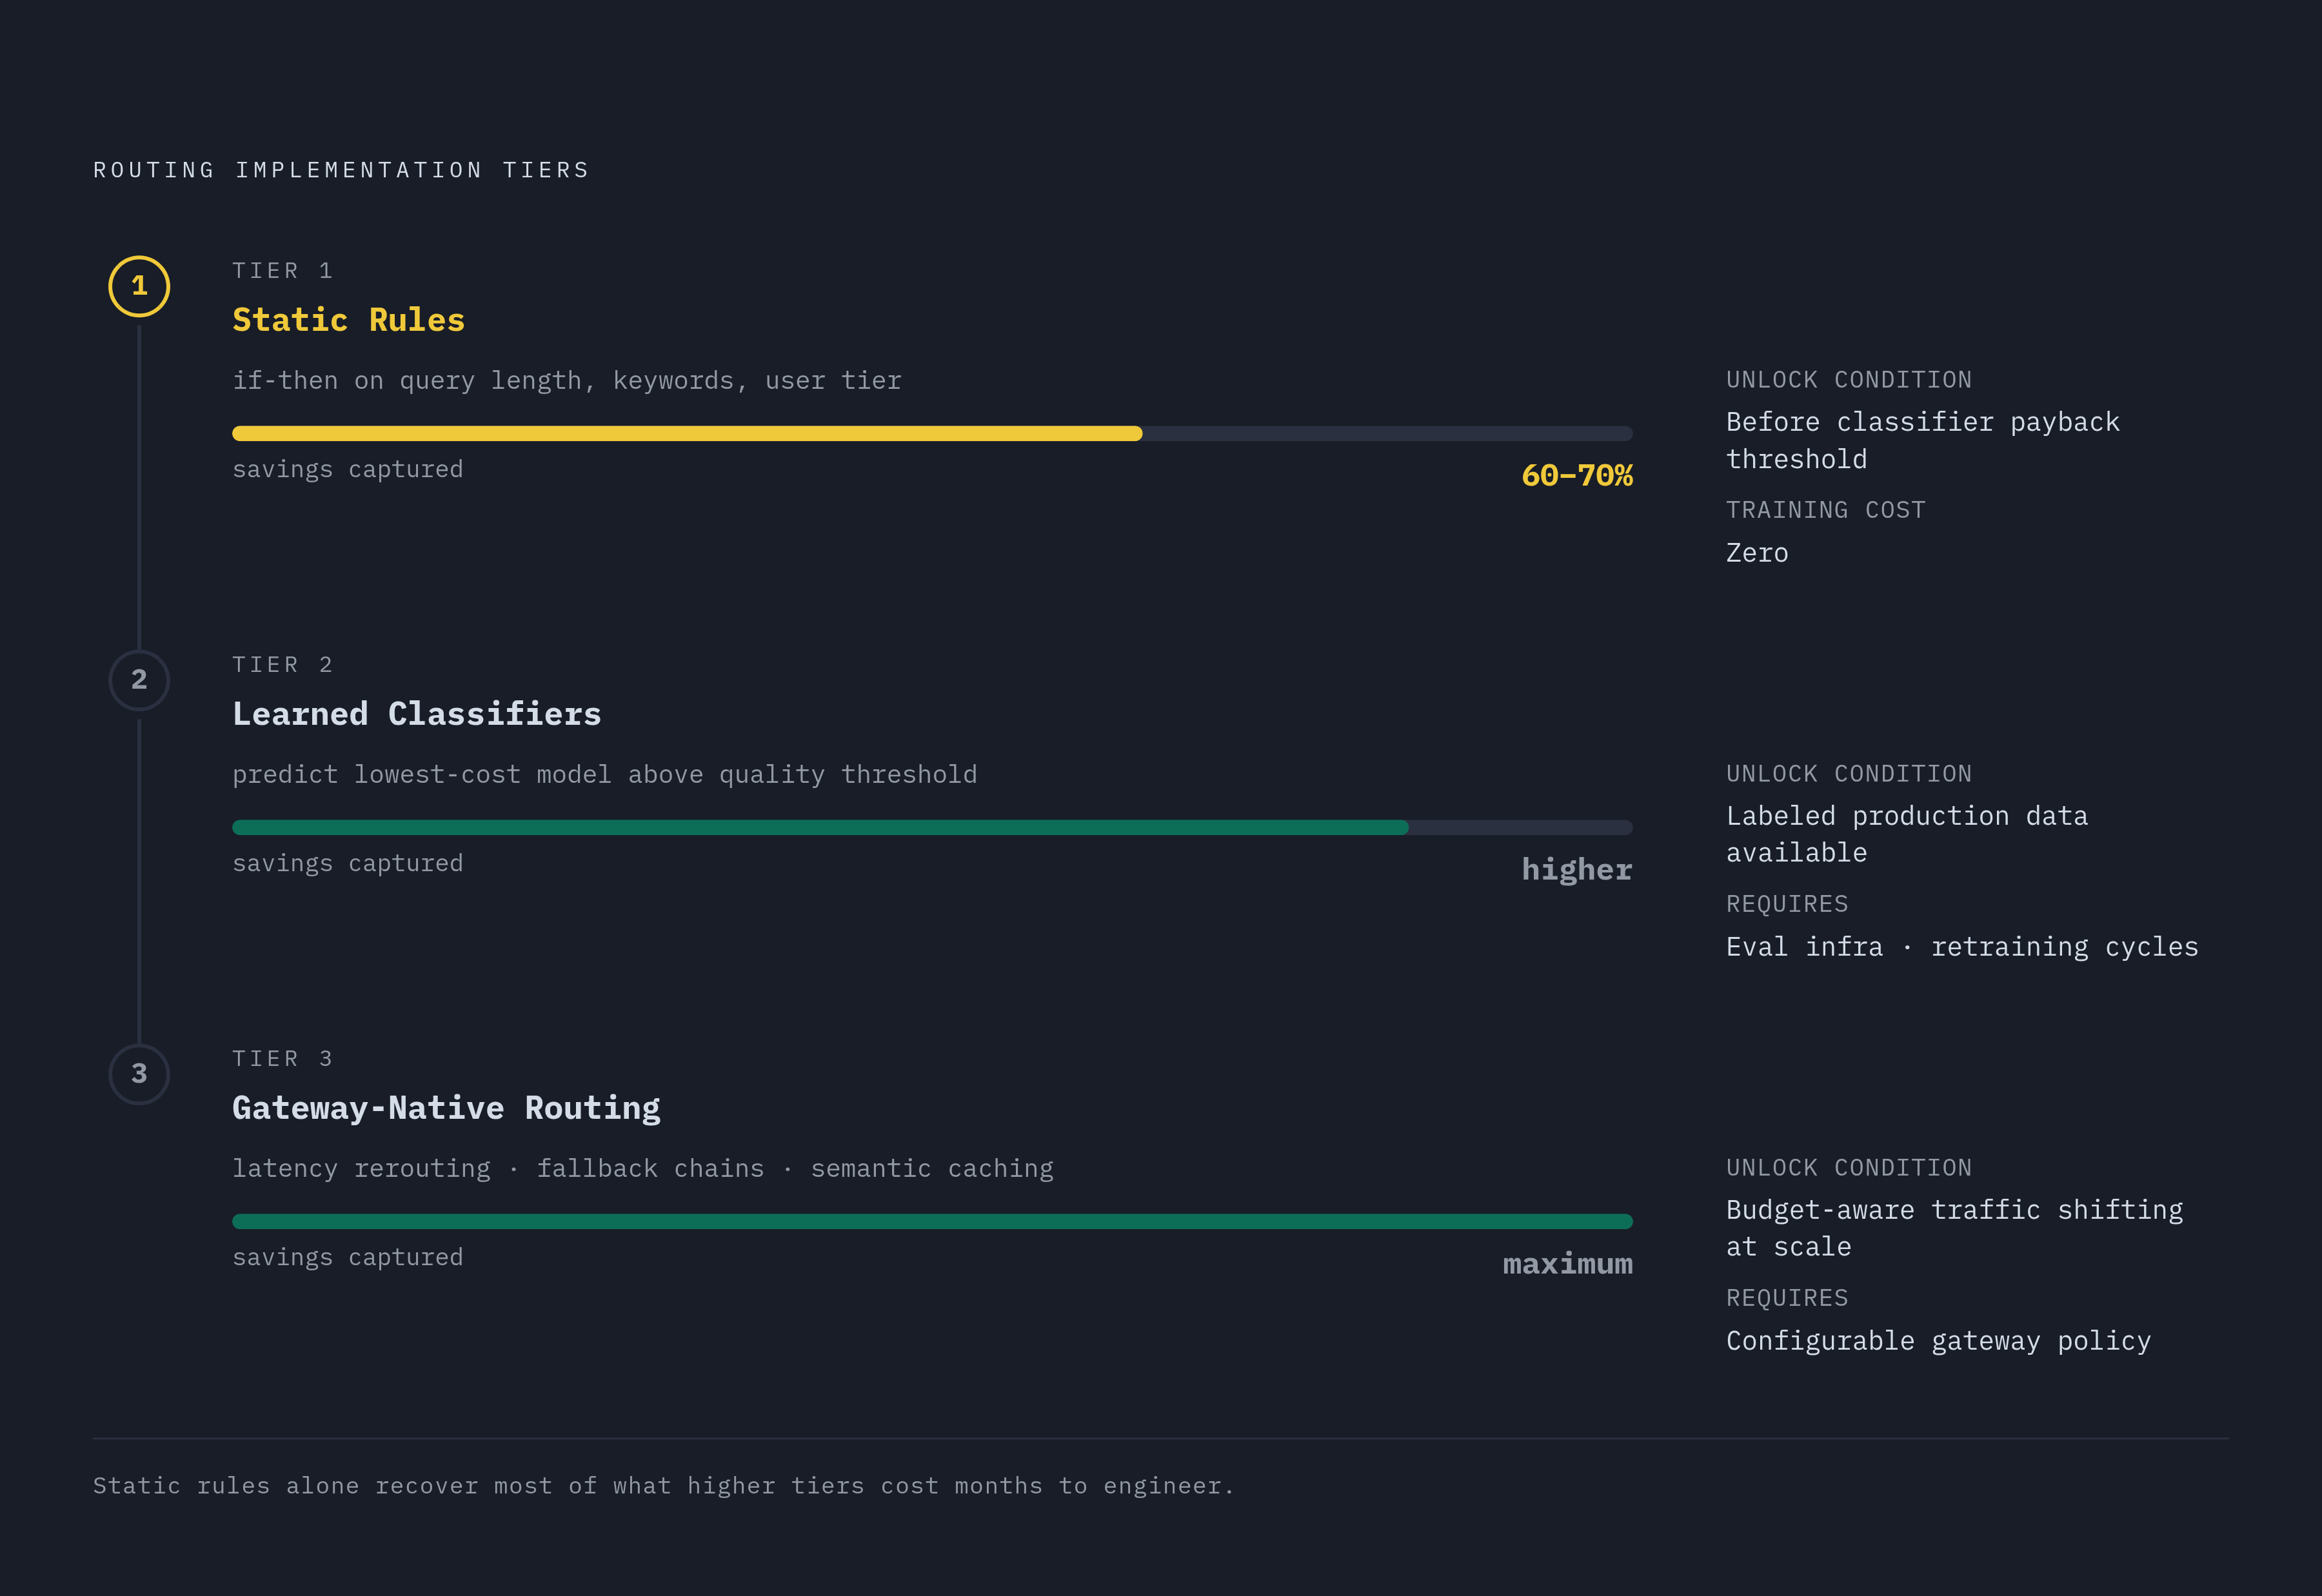
Once the three signals are defined per workload, the question becomes mechanical: how does an engineer actually encode "route this type of request to this model under these conditions" into a running system. There are three tiers teams build, and the right one to start with is determined by traffic volume and operational maturity, not by how sophisticated the engineering team wants to look.
Static rules are the first tier, and they're simple on purpose. They're if-then logic running against properties of the request that are already visible: query length, presence of certain keywords, which user tier is making the call, which endpoint got hit. A rule might send any request under a token threshold to a lower-cost model, route anything flagged as code generation to a model with strong coding benchmarks, or cap free-tier users to a cheaper provider by default. None of that requires training data or a model of its own, and it still captures the large majority of available savings, characterized as 60 to 70 percent of what's available, for zero training cost. Static rules are the right fit for teams whose monthly spend hasn't yet crossed the threshold where building and maintaining a classifier pays for itself.
Learned classifiers are the second tier. A classifier trained on labeled production data predicts which model will clear the quality threshold at the lowest cost for a given request type. That adds real savings beyond what static rules capture, but it comes with real costs attached: labeled training data has to exist, evaluation infrastructure has to be running, and the classifier has to be retrained as models and traffic patterns shift. This tier makes sense once volume is high enough that the engineering investment pays back, and only once a stable evaluation harness is already in place to make the classifier trustworthy.
Gateway-native intelligent routing is the third tier, where routing logic runs inside the gateway itself as configurable policy instead of application code. That includes latency-based rerouting around a provider that's currently degraded, fallback chains, and budget-aware routing that shifts traffic automatically as a model approaches its spend cap. Auto-rerouting around real-time provider failures or slowdowns is close to a requirement at this tier. Semantic caching also lives here, returning a stored response for a prompt that's semantically similar to one already answered, which cuts out a meaningful share of redundant model calls on real-world traffic. This tier suits teams that want routing intelligence without building and maintaining their own classifier, since managed gateway policy captures most of the available gains without the training overhead.
These tiers aren't stages a team graduates through and leaves behind. A mature setup runs all three at once. The sequencing argument is about earning the right to complexity. Static rules extract most of the value for free, so building a classifier before that value is captured is solving a problem that's already mostly solved.
Fallback routing as a quality and reliability guarantee, not just a backup plan
Fallback routing gets treated as an afterthought in a lot of production systems, something bolted on after the main routing logic is working, which is backwards. Fallback is the mechanism that makes every cost, speed, and quality decision upstream actually hold when a provider stops behaving the way it's supposed to.
Most implementations collapse every failure into one fallback rule, when there are three distinct categories, general, content-policy, and context-window fallbacks, that each need their own resolution strategy. General fallbacks cover timeouts and 5xx errors, the kind of outage that calls for simply trying a different model. Content-policy fallbacks cover a model refusing to answer a request, which needs a different model or a reformulated prompt, not just a retry. Context-window fallbacks cover a prompt that's too long for the model currently handling it, which needs a model with a larger context window, not a retry at all.
The sturdier design runs a separate circuit breaker per provider-and-model combination, so an outage on one model doesn't block requests that could still succeed on a different model from the same provider. The target worth building toward is failover that happens in under 200ms when a provider goes down, fast enough that the end user never notices anything happened.
The gateway itself becomes a single point of failure if nothing is done about it: if the gateway goes down, every feature touching an LLM goes down with it. The mitigations are concrete. A fallback path can live in application code as a last resort. A managed gateway can come with SLA guarantees instead of running as a single self-hosted instance. Multiple gateway instances can sit behind a load balancer with health checks watching each one.
The tradeoff between self-hosting and managed infrastructure isn't theoretical. On March 24, 2026, two malicious LiteLLM releases, versions 1.82.7 and 1.82.8, reached PyPI and were pulled after a short window. They harvested credentials from unpinned pip installs. The official LiteLLM Proxy Docker image, which pins its dependencies in requirements.txt, was unaffected. The lesson generalizes past this one incident: a team running a self-hosted proxy has to pin versions and own its own patch cycle, or it has to use a managed gateway where that work is somebody else's job.
What spend visibility requires to be useful for routing decisions
An invoice arriving at the end of the month tells a team what already happened. It can't tell a routing policy what to do next. Spend data only becomes useful as a routing input when it's granular, attributed by team, project, model, and provider, and available in close to real time.
AI spend doesn't behave like a typical SaaS budget line, where usage is roughly predictable per seat. One employee running a tool for email summarization might use a few thousand tokens a day. Another employee using the exact same tool for complex code generation might use many millions.
Uber's own CEO acknowledged that the company burned through its entire annual AI budget inside a single quarter. That wasn't only a budgeting failure. It was a routing failure, because no signal existed at the time that could have redirected cheaper-fit traffic before the spend got away from anyone watching. A routing layer with real-time cost attribution is exactly the kind of signal that incident was missing.
Token prices have fallen substantially year over year across providers, and the intuitive assumption is that falling prices should ease the governance burden. The opposite has happened. Total enterprise AI budgets have grown, because cheaper tokens make more use cases financially viable, which pulls more workloads and more teams into the system at once. Falling unit cost doesn't ease the governance burden; it raises it. It accelerates it, by giving more people a reason to spend without anyone watching the aggregate. Granular, real-time, correctly attributed cost data is what turns that spend from a surprise on an invoice into a signal the routing layer can act on before the budget is gone. Some teams handle this through a model router like Concentrate AI, a managed AI gateway that tracks spend by model, provider, API key, and project in real time and enforces budget limits without requiring teams to host or maintain any proxy infrastructure.