Finance Stakeholder Visibility Into AI Usage and Spend
Finance needs real-time visibility into AI spend by team, model, and provider.
Most finance teams still govern AI spend the way they govern a SaaS subscription: a fixed seat cost, checked once a quarter, filed away until the next renewal. AI token spend does not behave that way. It behaves like infrastructure, consumption-based and usage-driven, with the ability to grow faster than any approval cycle finance has in place.
Agentic workflows drive that growth. A single user action can trigger a chain of model calls, each one spawning the next, and the token consumption stacks up in ways no one reviewing a monthly invoice would ever catch in time. By the time the bill lands, the workflow that caused the spike has already run thousands more calls.
The scale of the blind spot is already measurable. KPMG Global's AI Pulse Q2 2026 survey found that a substantial share of senior leaders have only partial visibility into AI spending, and a quarter of organizations cannot even identify what AI systems are running inside their own environment. That second number is not a footnote about messy internal reporting. An organization that cannot say what AI systems it has running cannot audit them, cannot budget for them, and cannot govern them in any meaningful sense.
So the invoice cycle itself is the failure point. Finance finds out what happened. Finance never finds out what's happening as it happens, and by the time a number appears on a statement, the decision that produced it is long gone.
The four dimensions finance needs for granular AI spend visibility
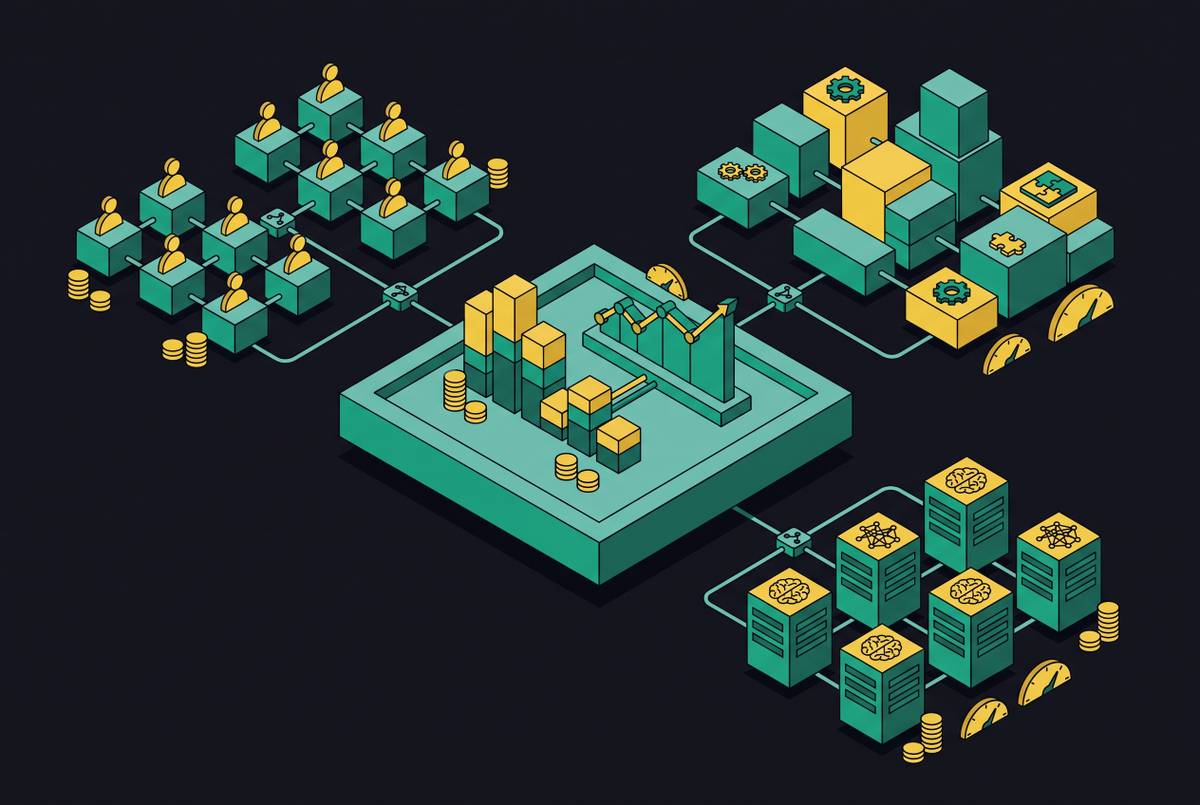
Real visibility means more than a dashboard with a bigger number on it. It means finance can answer a specific question on any given day: who spent this, on what, using which model, through which provider. Attribution has to happen at all four of those levels at once, because without that granularity, finance cannot identify waste, cannot enforce a budget, and cannot run a chargeback.
Team-level attribution is the foundation. It tells finance which business unit or engineering squad actually generated a given slice of spend, and it's the only basis for holding a budget owner accountable. Project or workflow-level attribution goes a layer deeper: it separates a production feature earning its keep from an experimental pipeline burning tokens nobody's watching. Model-level attribution answers a different question entirely, whether a task assigned to a premium frontier model could have run just as well on a cheaper tier. And provider-level attribution matters because pricing, rate limits, and outage risk differ materially from one API endpoint to another.
Miss any one of those four dimensions and finance is left staring at a total token bill with no way to explain it. The question "why did spend jump this month" has no answer. Neither does "which team is responsible".
The tooling most finance departments already own was never built for this. Spend management platforms were designed around seat-based SaaS contracts and fixed monthly costs tied to headcount, leaving them unable to handle consumption-based pricing, prepaid credit pools, or the hybrid seat-plus-consumption plans that AI providers increasingly sell. That's a tooling gap, not a process failure finance can fix by tightening its review cadence.
Provider dashboards don't close that gap either. They show total consumption at the account level, but they were never designed to attribute that consumption across internal teams or projects. Ramp's July 2026 launch of AI Token Spend Management was built directly against this problem, offering a single dashboard across AI providers with weekly usage briefings and real-time alerts, because without cost allocation, organizations have no way to identify or optimize expensive AI usage.
The LLM gateway as the source of truth for spend data
A spend record finance can actually use has to be produced at the one layer that sees every model request before it leaves the building. That layer is the LLM gateway. Not the provider dashboard, and not scattered application logs.
The logic here is straightforward. Every call to a model, from every application in the organization, crosses the gateway on its way out to a provider. That single choke point is the only place in the entire stack with complete, consistent visibility across every team and every provider at once. Without it, the logic for routing, budgeting, and observability has to live inside every individual application separately, fragmented, inconsistent, and invisible to anyone in finance trying to make sense of it.
The fragmentation gets worse, not better, as usage grows. Gartner forecasts that 40% of enterprise applications will embed task-specific AI agents by the end of 2026, up from a small fraction in 2025. Each of those agents multiplies the number of model calls per task, and the gateway is the only control surface built to absorb that.
The governance primitive that makes this work in practice is the virtual key. A virtual key bundles access permissions, budget limits, and rate limits into a single entity that can be attributed to one team, one project, or one customer, and spend tracked against that key is the unit finance can actually read and act on. Hierarchical budget controls sit on top of that structure, letting finance and engineering agree on spend envelopes per team or business unit, with hard enforcement that blocks a request the moment a threshold is crossed rather than flagging it after the fact.
The chargeback model, making teams accountable for the spend they generate
Visibility on its own doesn't change anyone's behavior. It has to be paired with accountability, and the chargeback model, already proven in cloud cost management, is the same lever applied to AI spend.
Anyone who has lived through a cloud FinOps rollout will recognize the shape of this immediately. The same incentive structure applies here: when AI spend gets allocated back to the team that generated it, that team has a direct reason to cut waste, the exact mechanism that made cloud FinOps work in the first place. Without that allocation, AI spend just sits as a shared cost center that no individual team has any reason to optimize.
The gateway's virtual key structure is what makes this technically doable. Spend gets tagged at the request level as it happens, so a monthly allocation report doesn't require anyone to reconstruct anything by hand. Finance can set a budget envelope for a team ahead of time, and the gateway enforces it in real time.
Chargebacks also surface waste that would otherwise stay invisible. A recurring pattern is teams defaulting to a premium frontier model for routine tasks a cheaper tier would handle just as well. Ramp's AI Token Spend Management data shows that only about 50.8% of businesses connected to OpenAI's API have enabled prompt caching, so roughly half are paying full input-token prices on calls that could be substantially cheaper. A chargeback model is what gives a team the incentive to actually go close that gap, since routing policy enforced at the gateway can correct model-tier selection by team or workload without anyone touching application code.
Real-time alerting and budget controls finance should require
An alert and a block are not the same category of control, and finance needs to be clear about which one it's actually getting. An alert that fires once spend crosses a threshold is useful information. A hard block that stops requests from a team that has already burned through its budget is governance. That distinction matters the moment a runaway agentic loop starts exhausting a monthly budget in minutes rather than weeks.
Finance should walk into any vendor conversation with a specific list of requirements instead of a general sense that "better visibility" would help. Per-team and per-project budget caps need hard enforcement behind them instead of a dashboard flag. Rate limits need to cap token consumption within a time window, not just count the number of requests going through, because request counts tell finance almost nothing about actual cost. Real-time dashboards need to be readable by someone outside engineering, without that person needing a login to internal tooling they were never trained to use. Weekly usage briefings and trend reporting, the kind Ramp's July 2026 AI Token Spend Management product includes, give finance a regular cadence to check in on without needing to babysit a live dashboard all day. Token-based rate limiting is the only unit that actually governs AI cost, since a single request can swing by orders of magnitude in both token consumption and price depending on what it's doing.
All of these specific asks depend on one structural requirement. Budget controls need to be hierarchical, set at the organization level, the team level, and the individual application level, with enforcement that happens automatically rather than depending on someone remembering to check. That hierarchy should mirror how finance already reports internally. If it doesn't, the tooling will always feel like it's fighting the org chart instead of supporting it.
Security and compliance obligations that attach to AI spend visibility
The infrastructure that gives finance spend visibility and the infrastructure that gives security team data governance turn out to be the same infrastructure. Organizations that procure them as two separate projects usually end up building the wrong thing twice, and neither finance nor security should be treating AI governance as a problem that belongs solely to the other team.
A large share of AI prompts carry sensitive data, and when a provider retains logs by default, every one of those unguarded API calls is a potential GDPR or HIPAA disclosure. Default retention terms are not uniform and not always obvious. OpenAI retains API data for up to 30 days for abuse monitoring by default, Anthropic cut its standard API log retention down to a matter of days in September 2025, and zero-data-retention terms require a separately negotiated enterprise agreement that isn't available on a standard pay-as-you-go plan.
The gateway sits on the request path already, which makes it the natural place to enforce PII redaction before a prompt ever reaches a provider, and to generate audit logs at the metadata level, timestamps, token counts, policy outcomes, without logging the prompt content itself. Role-based access control and SSO are the organizational controls enterprise security teams require on top of that, and the same virtual key structure that makes chargebacks possible also enforces who is allowed to call which model with what kind of data.
Boards and regulators have started asking for proof, not assurances. Quarterly reporting increasingly includes requests for an AI Bill of Materials, and finance stakeholders are now being asked to show not just what AI cost, but what AI actually ran, who controlled it, and where sensitive data ended up. JPMorgan and Uber both built out governance infrastructure, policy enforcement, agent identity management that extends enterprise SSO to AI agents, infrastructure-level PII redaction, and audit logging, before scaling further; Uber's governance stack was in place before the company scaled to a high volume of AI-generated code changes running every week. Approving AI spend without requiring that compliance layer alongside it means approving a liability, whether or not anyone frames it that way at the time.
Evaluating whether your AI infrastructure can deliver spend visibility
Most organizations don't discover their AI visibility gap during a planning cycle. They discover it during an incident, a budget overrun, a compliance audit, a provider outage, and by that point the cost of not having known sooner is already locked in.
A finance leader can run a fairly short diagnostic in a single conversation with an engineering lead, without needing to understand gateway architecture. Engineering should be able to show spend broken down by team and project live, rather than reconstructed after the fact from last month's invoices. Can they show which models each team is calling and what each of those calls actually costs? Can a hard budget cap get placed on a team without anyone needing to write new code? And does anyone know which prompts contain PII, and whether those prompts reached a provider operating under a retention policy that keeps that data around?
If the answer to any of those is "we'd have to pull logs" or "we'd need to build that," the gap is structural. It's structural. The most common root cause is the absence of a unified gateway: without one, spend data ends up scattered across provider dashboards, individual application logs, and team-level API keys that share no common attribution scheme. A related pattern occurs in teams that reached for a provider-abstraction tool early to handle multiple model providers, then hit real limits once traffic grew, with retries stacking on retries and no clean token-level cost breakdown available anywhere. That pattern is usually a sign the infrastructure layer got built for developer convenience rather than for the kind of production governance finance actually needs. None of these questions require a gateway RFP to ask. They're the kind of thing a CFO or VP of Finance should be comfortable raising in a normal budget conversation.
Build vs. buy decisions for the gateway layer that finance and engineering must make together
Whether to self-host a gateway or buy a managed one is not a call engineering should make alone, because the deciding factors are data residency, operational burden, and which governance features ship in the core product, not raw technical performance.
Self-hosted gateways keep every byte of data on the organization's own infrastructure, which makes them the right answer for regulated industries or any organization under strict data residency requirements. Engineering owns operations, upgrades, and reliability for that system going forward, indefinitely. Managed gateways move that operational burden onto a vendor in exchange for a platform fee, though in some cases they can't route prompts through a private network, which disqualifies them outright for certain compliance regimes. OpenRouter's published credit fee offers a useful public benchmark for what the managed layer actually costs, and that number should get weighed against token spend volume plus the engineering hours self-hosting would consume before anyone assumes self-hosting comes out cheaper at scale.
The governance features finance actually needs, hierarchical budgets, role-based access control, immutable audit logs, SSO, vary a lot across the options on the market. Some vendors ship all of that in the core product. Others gate it behind an enterprise tier that costs considerably more. That's the question finance should be pressing on in a vendor conversation, not latency benchmarks that engineering can evaluate on its own.
A production-grade gateway holds up under real load and ships its governance layer standard rather than behind a paywall, and a gateway that fails either test rarely survives a serious platform review once it's actually put in front of one. For organizations where engineering capacity is limited and AI usage is growing faster than that capacity can keep up with, a managed gateway connecting to more than 70 providers through one unified API, with no separate provider keys, no bespoke integration code, and no self-hosted infrastructure to maintain, solves the operational side of this problem directly. The decision connects the two concerns so neither finance nor security is managing AI in isolation.