Setting and Enforcing LLM Spend Limits Across Engineering Teams
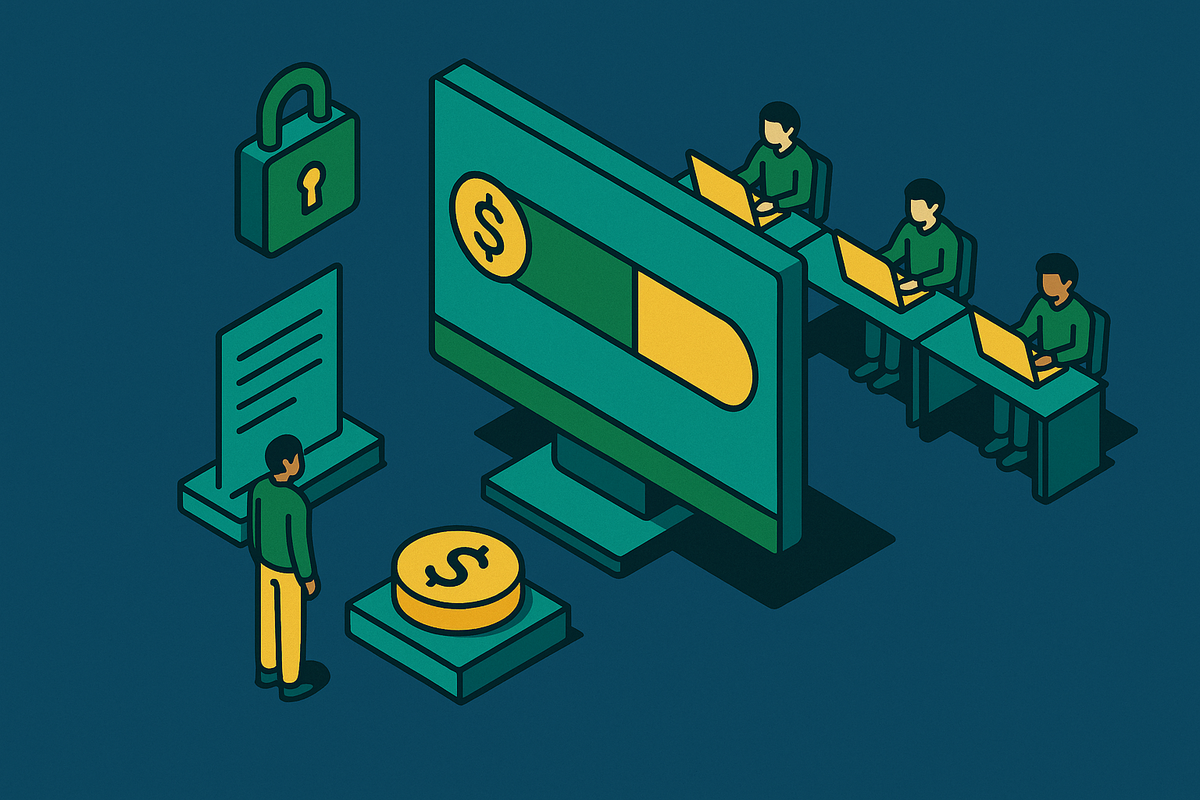
A gateway layer lets you measure and cap LLM spending before the bill arrives.
Søren Achebe
Contributing Editor, LLM Systems
Søren holds a background in distributed systems research and spent five years as a staff engineer at a model-serving startup before transitioning to editorial work focused on the technical plumbing behind large language model deployment. His coverage emphasizes architectural trade-offs that practitioners actually face in production.
8 stories
A gateway layer lets you measure and cap LLM spending before the bill arrives.
Measure latency against your own traffic, not published benchmarks.
A gateway centralizes LLM routing, caching, and cost tracking across multiple providers.
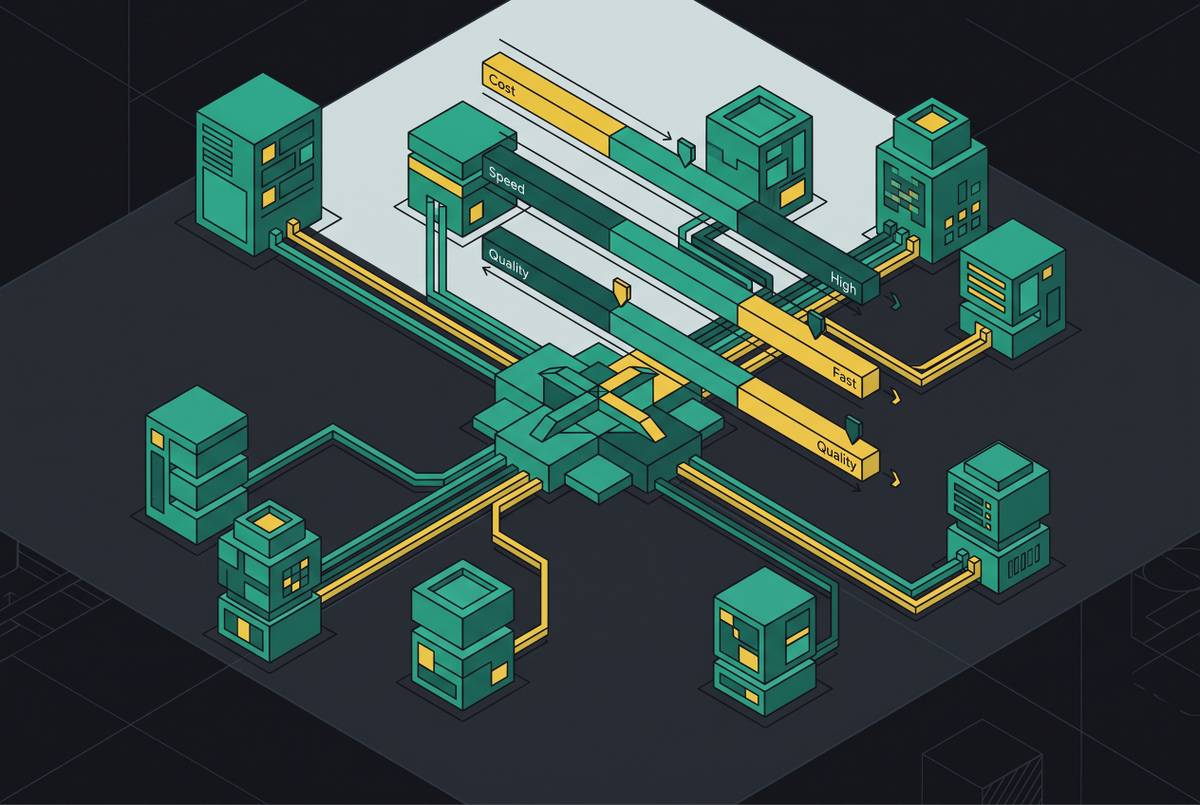
Treat cost, speed, and quality as equal routing signals, not a hierarchy where quality always wins.
Sessions, traces, and spans let teams debug LLM failures.
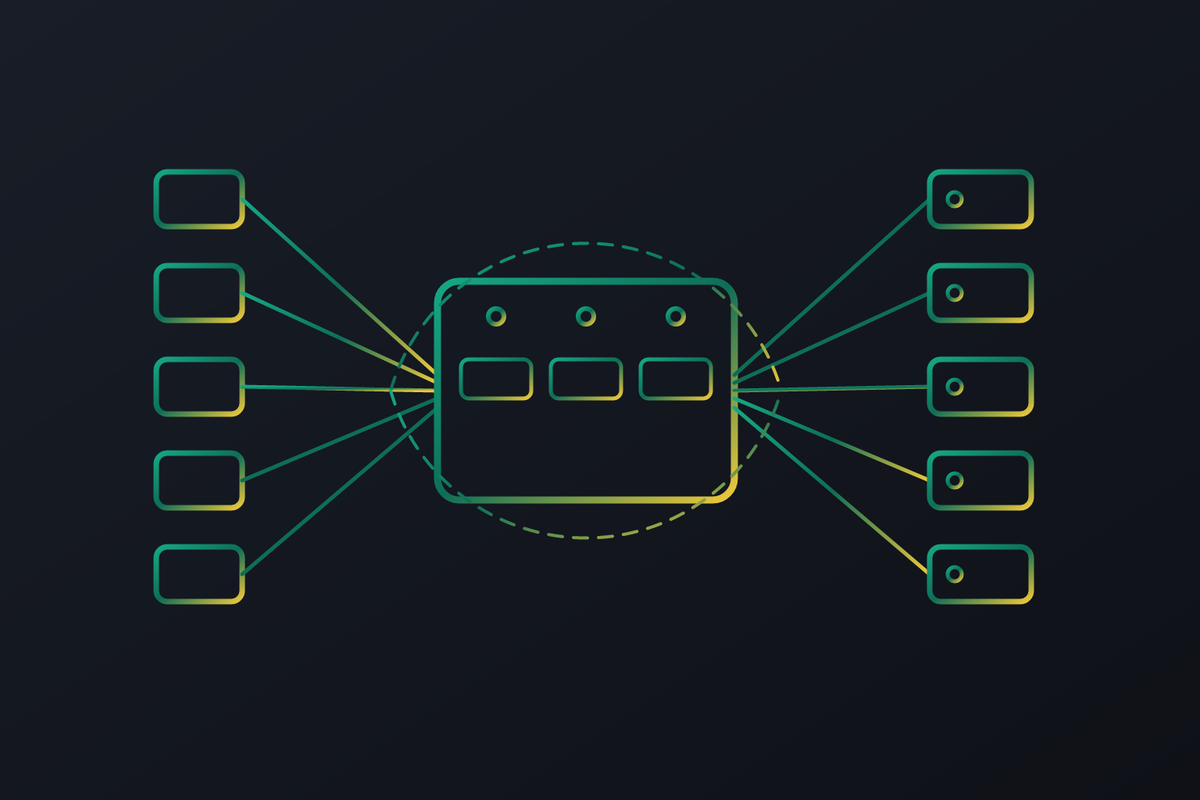
One unified API replaces scattered provider integrations across your services.
A gateway layer handles rate limits the tier structure won't, through queuing and smart routing.
A reverse proxy that unifies multiple LLM providers, credentials, and spend tracking in one place.